Projects
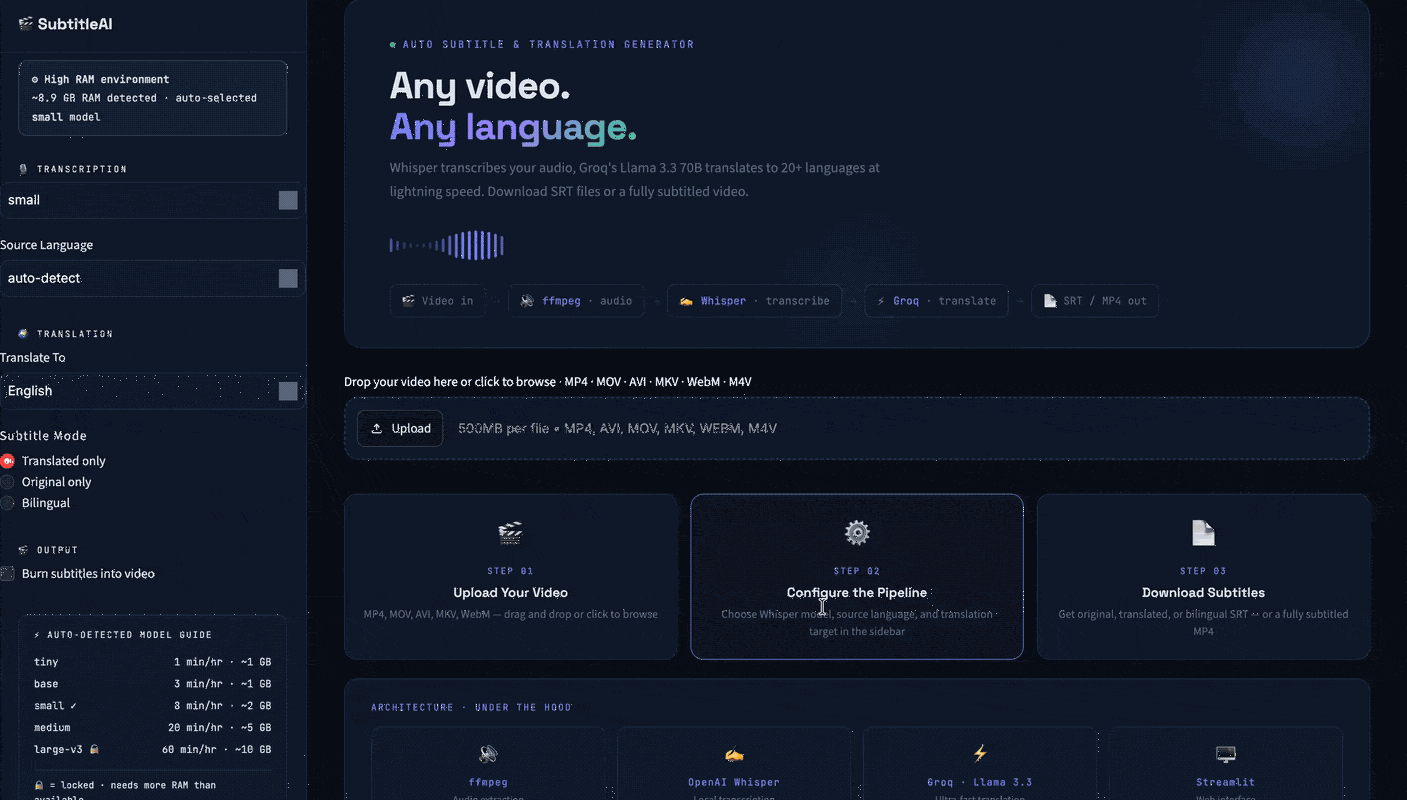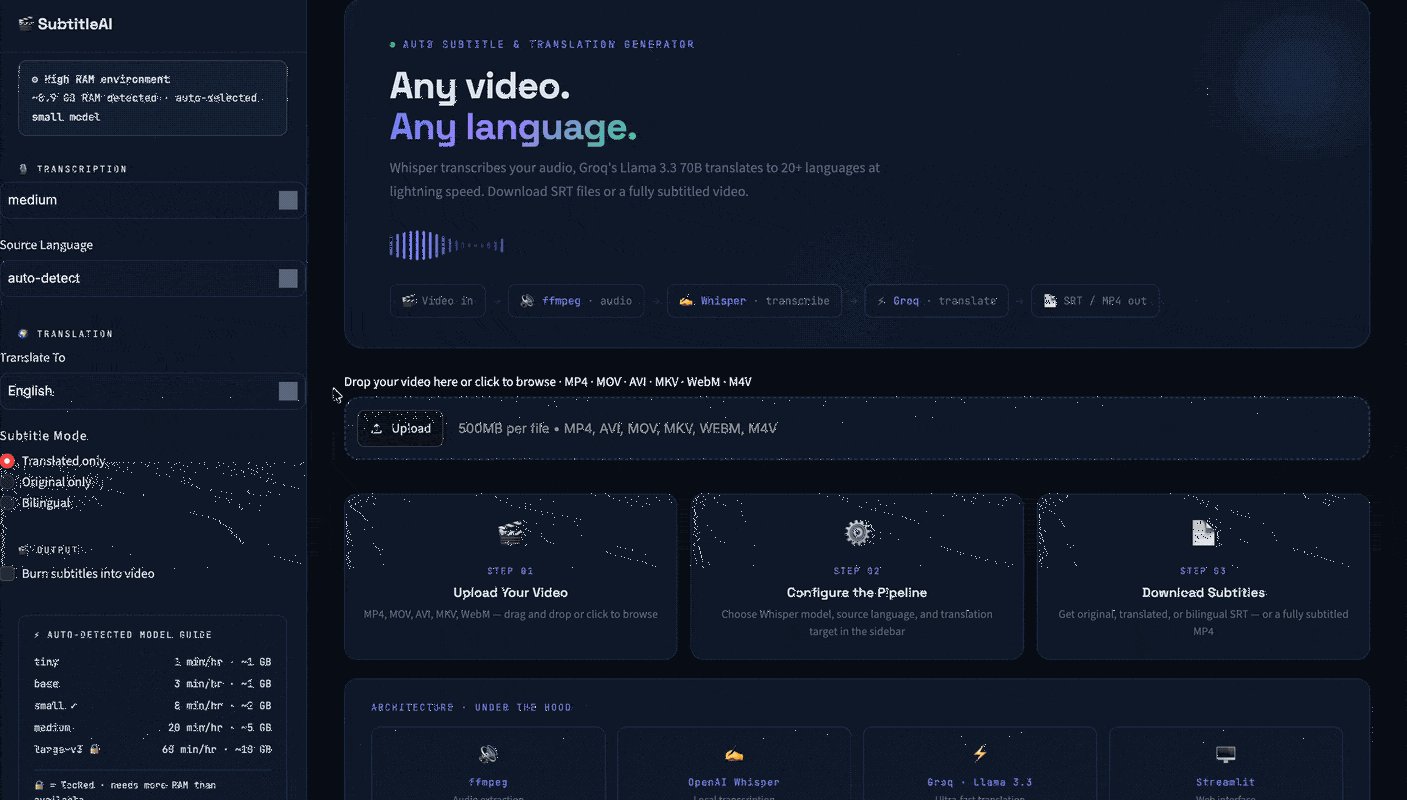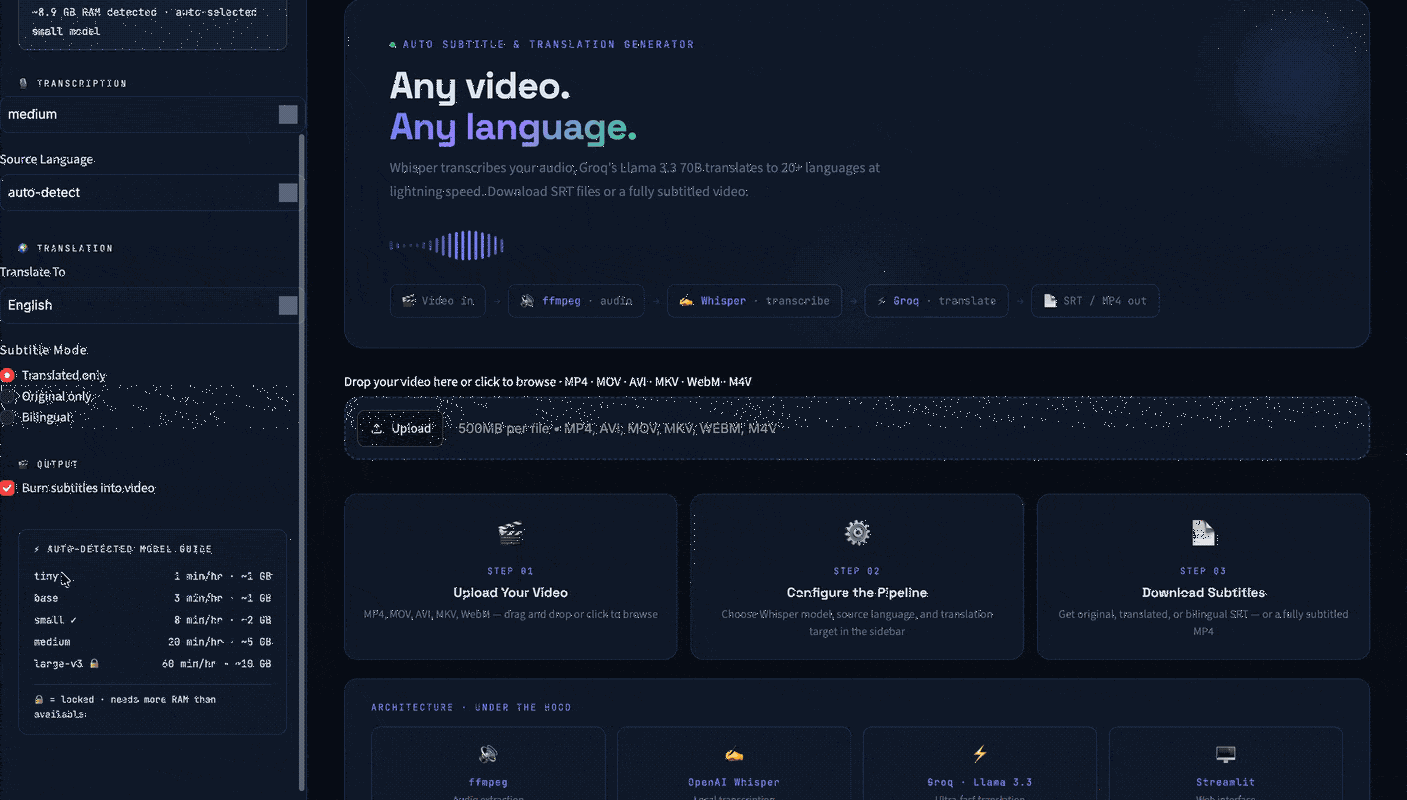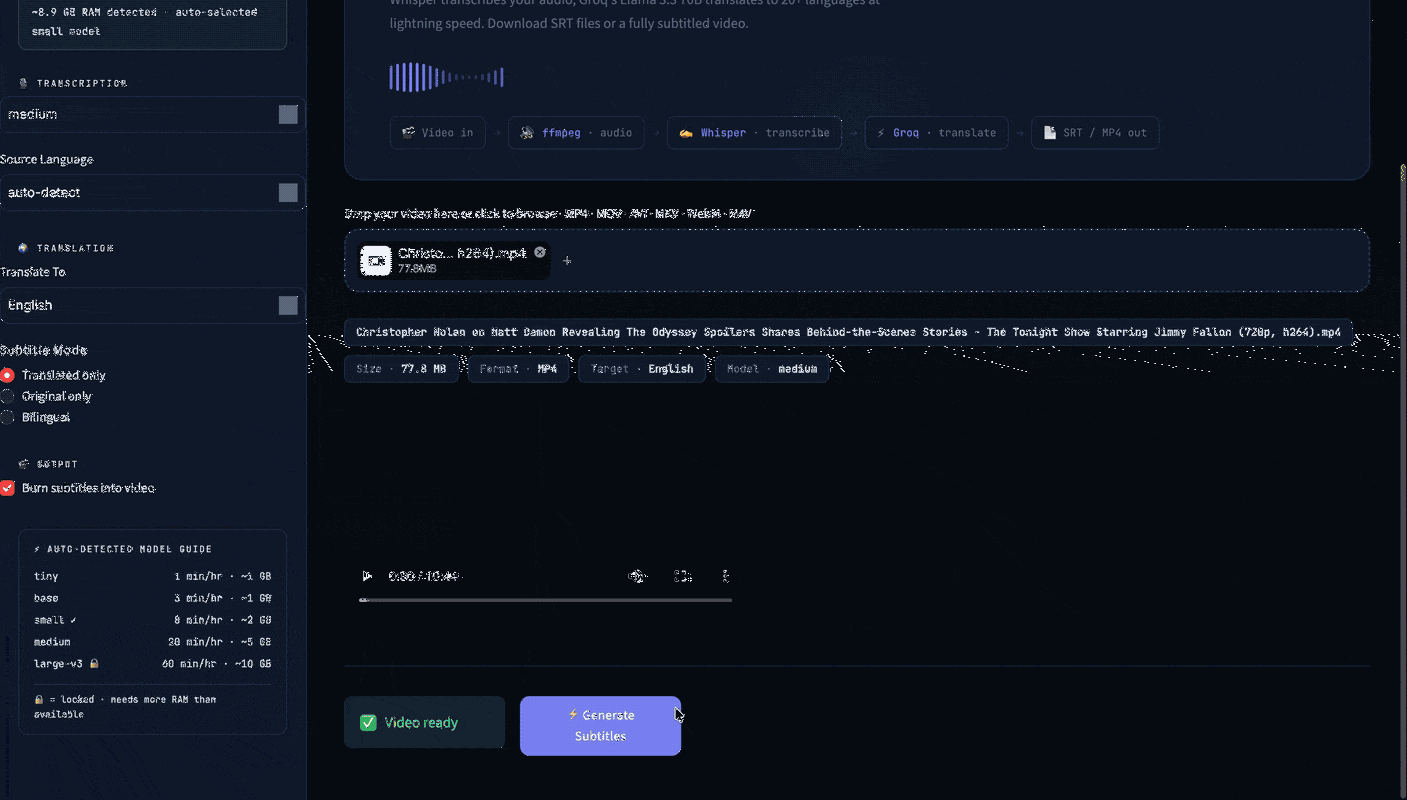
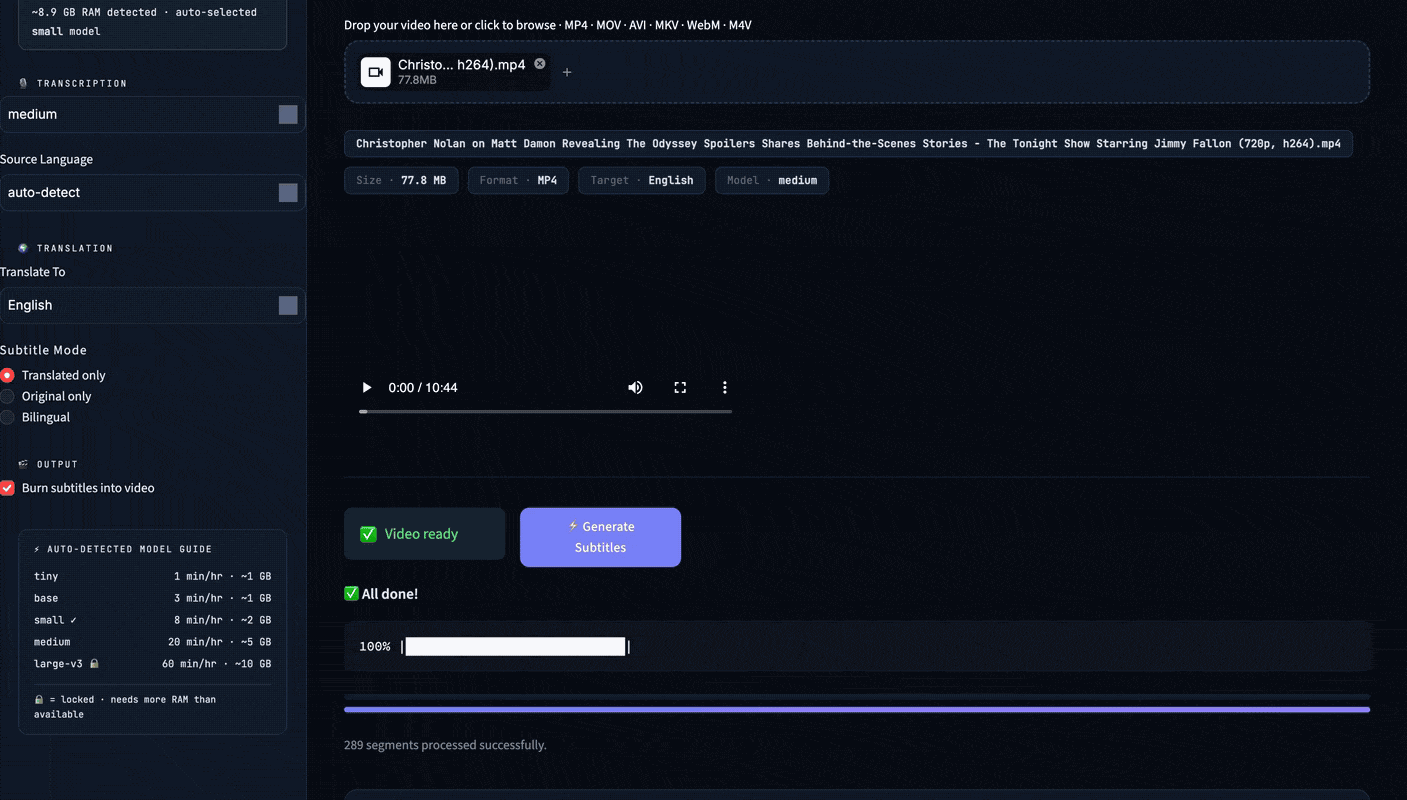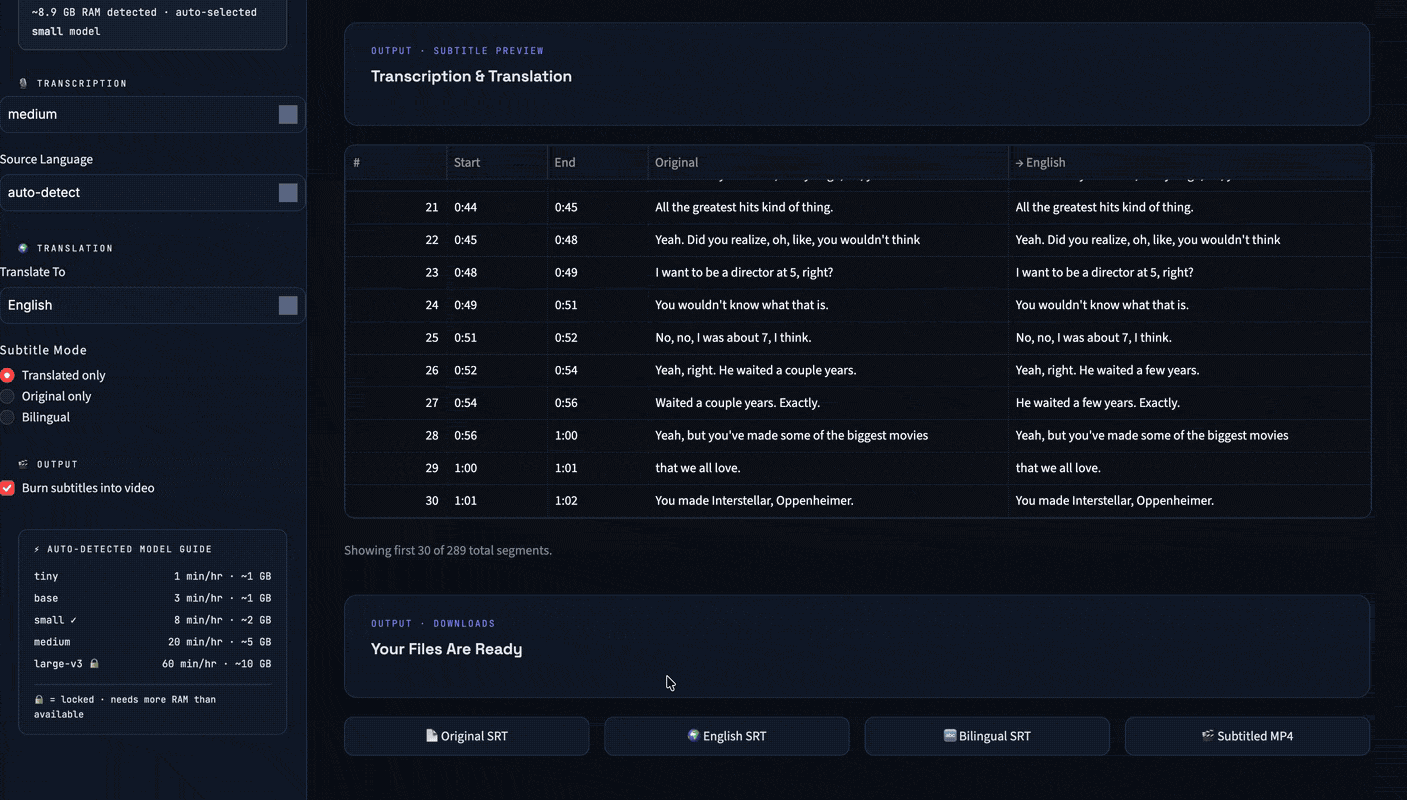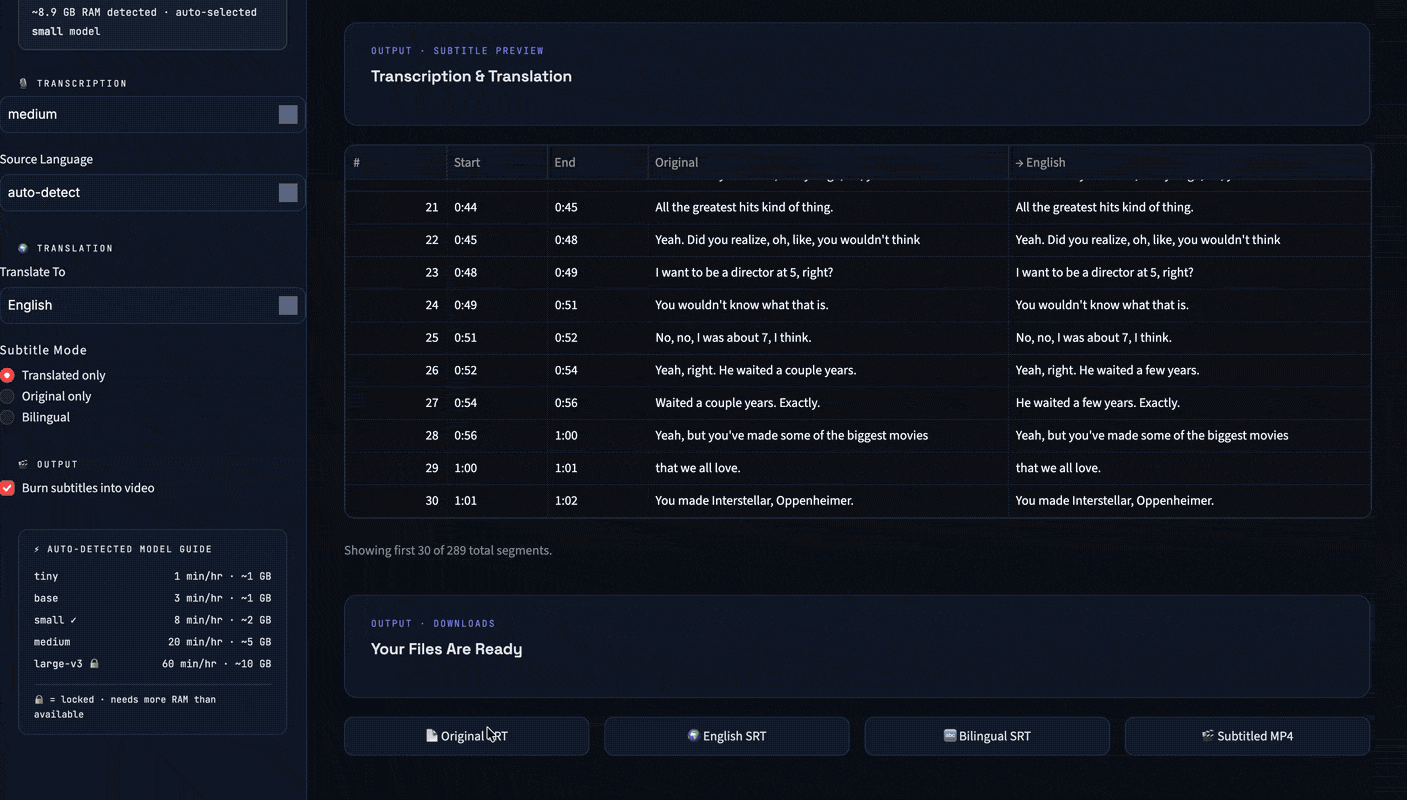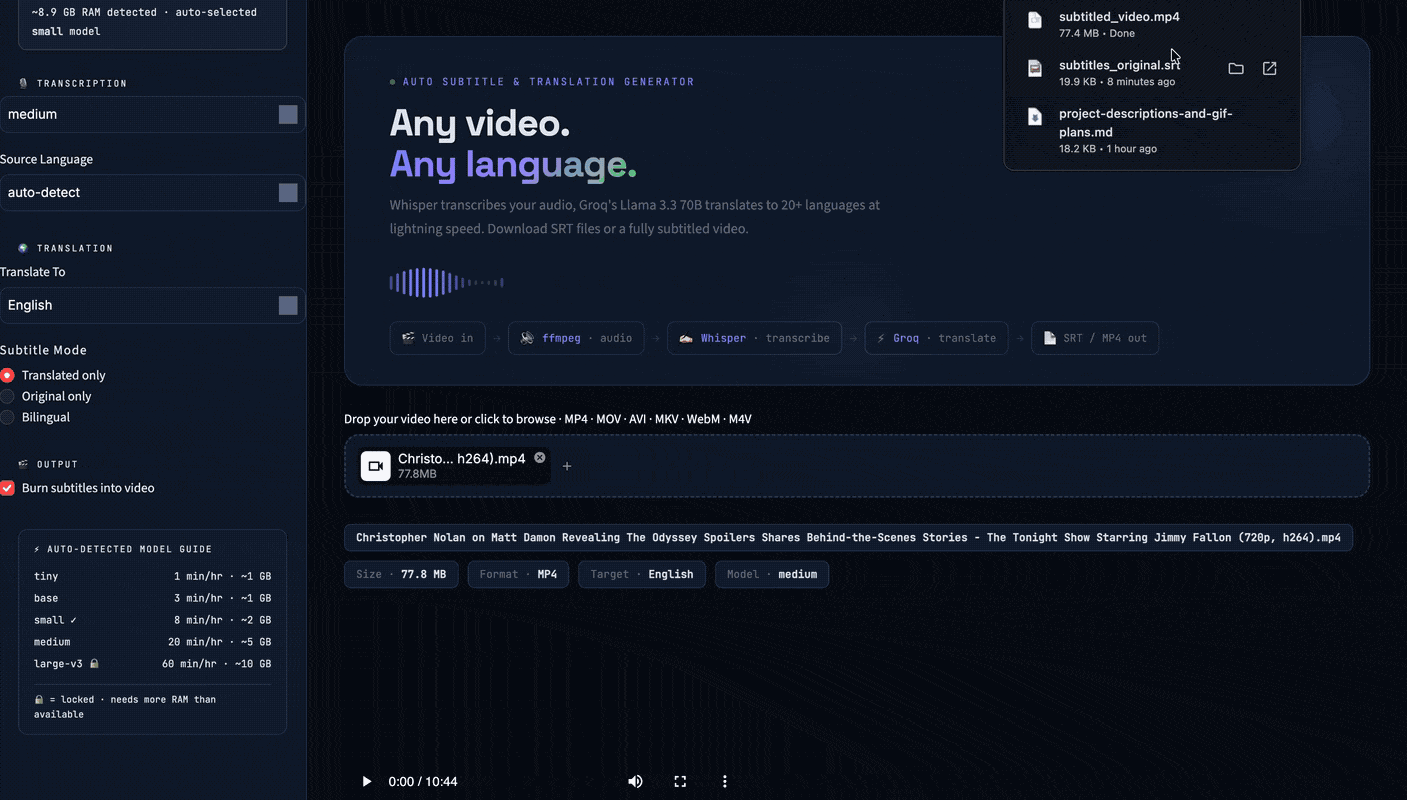
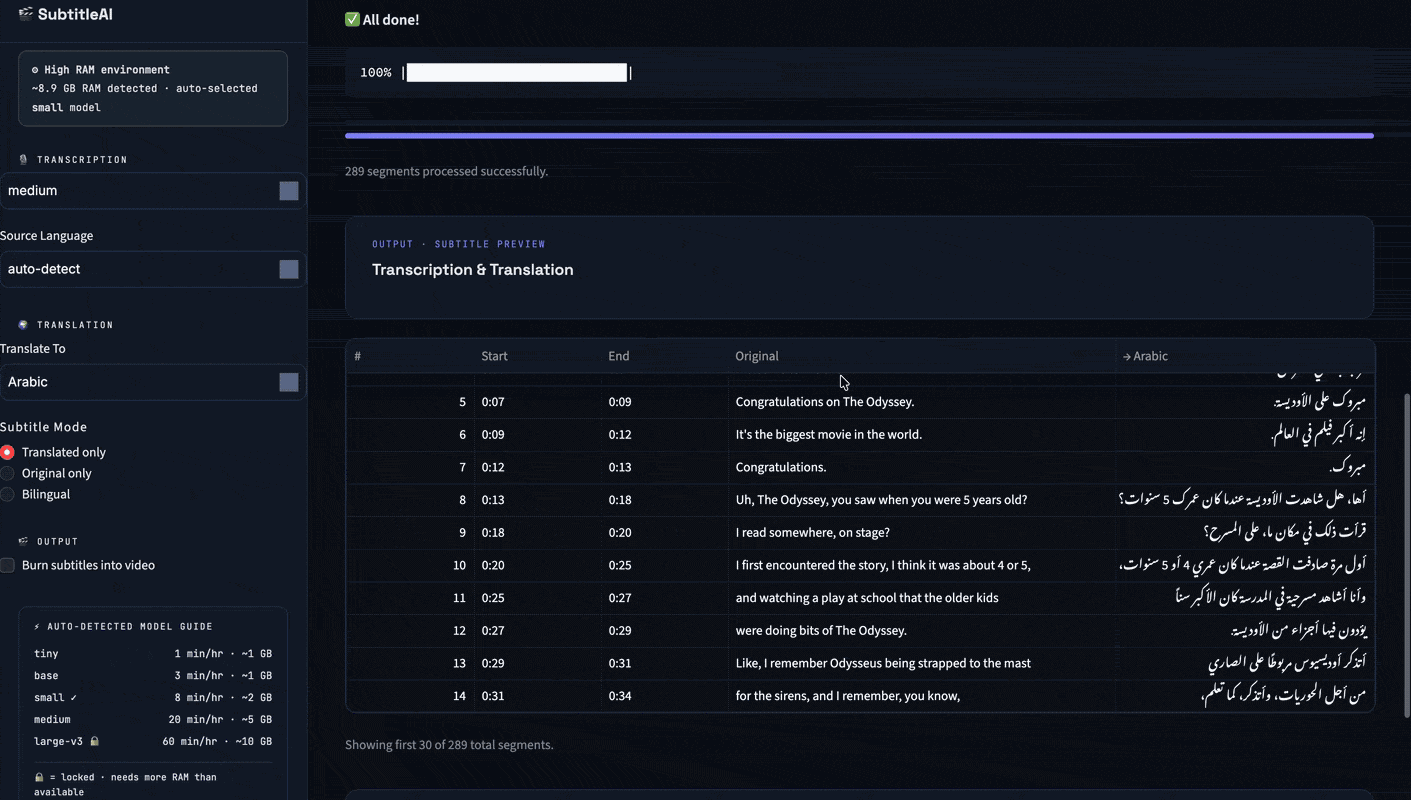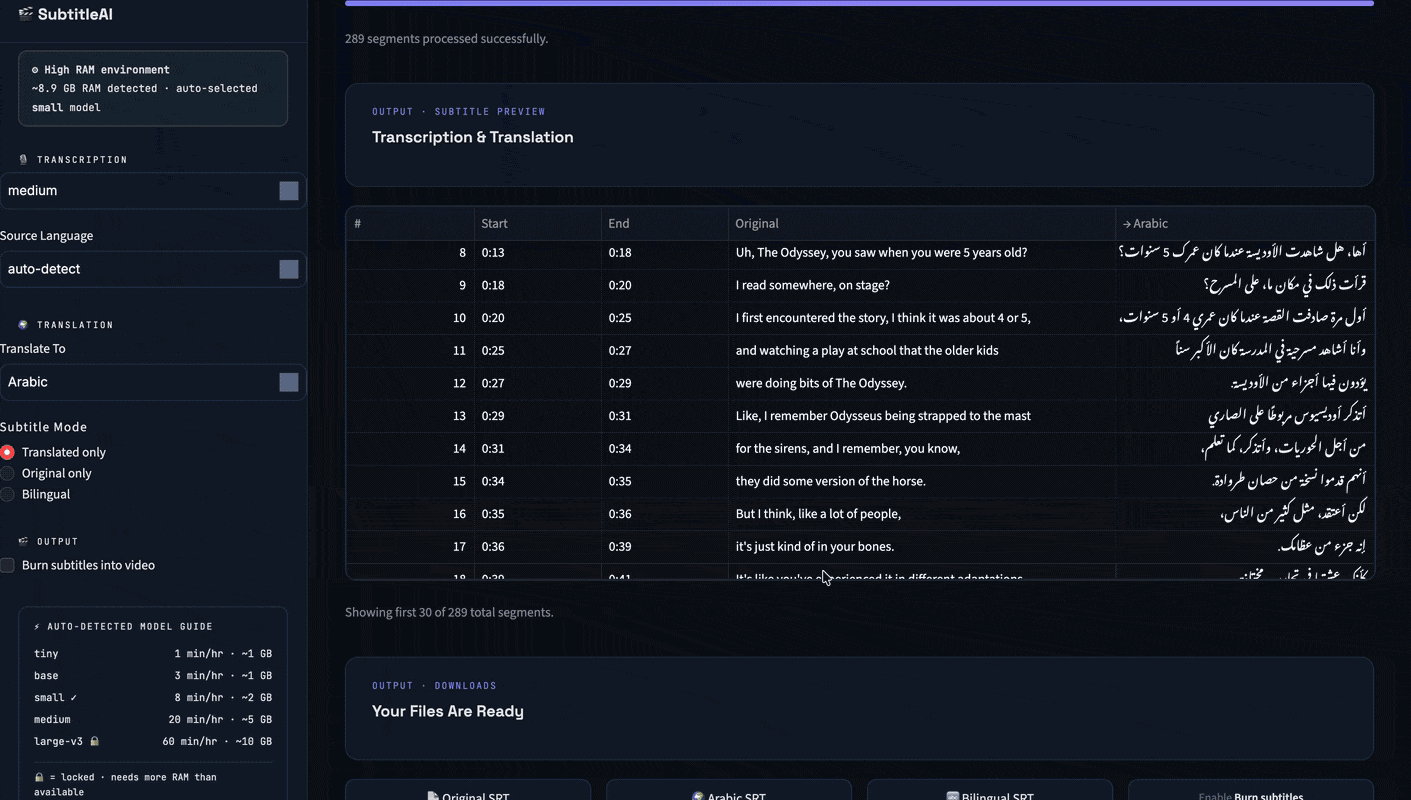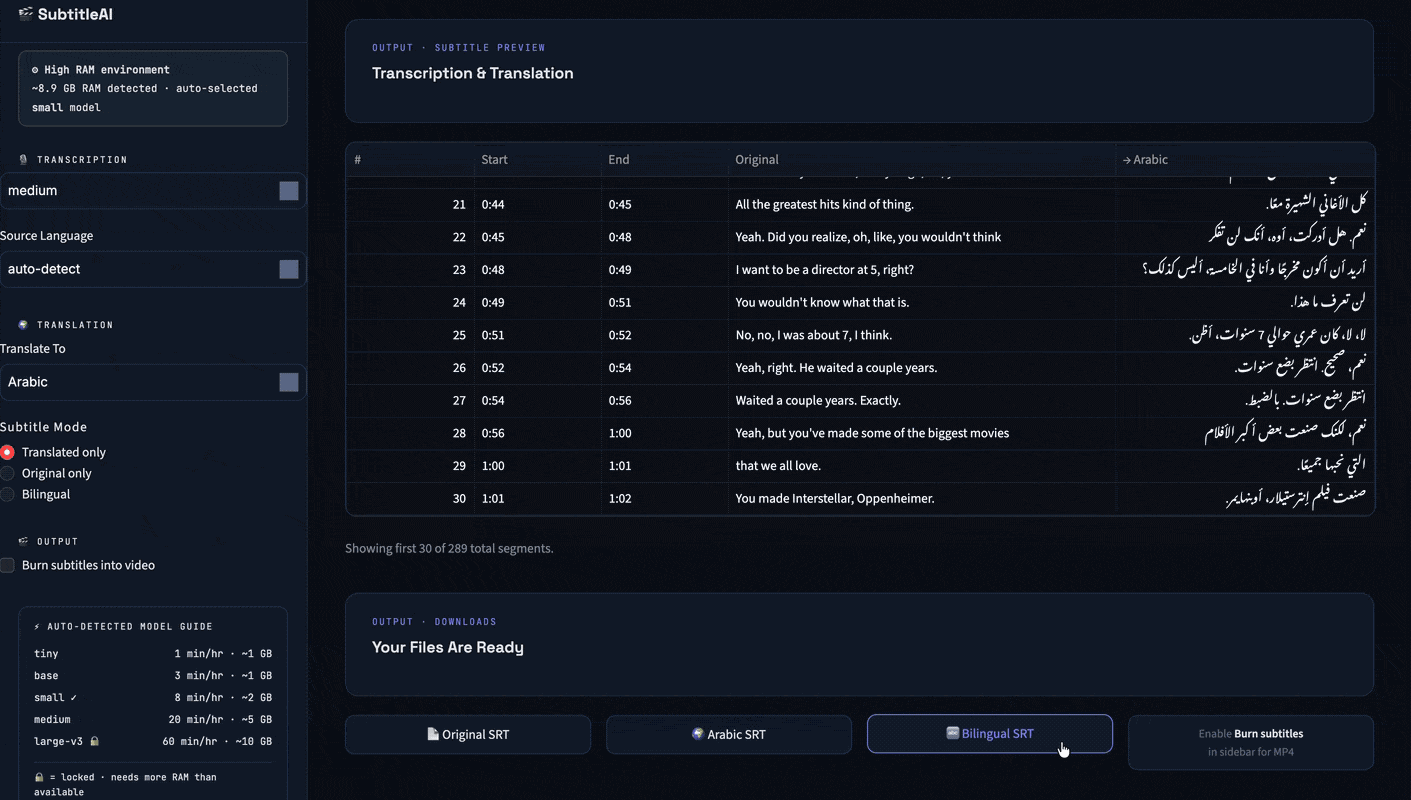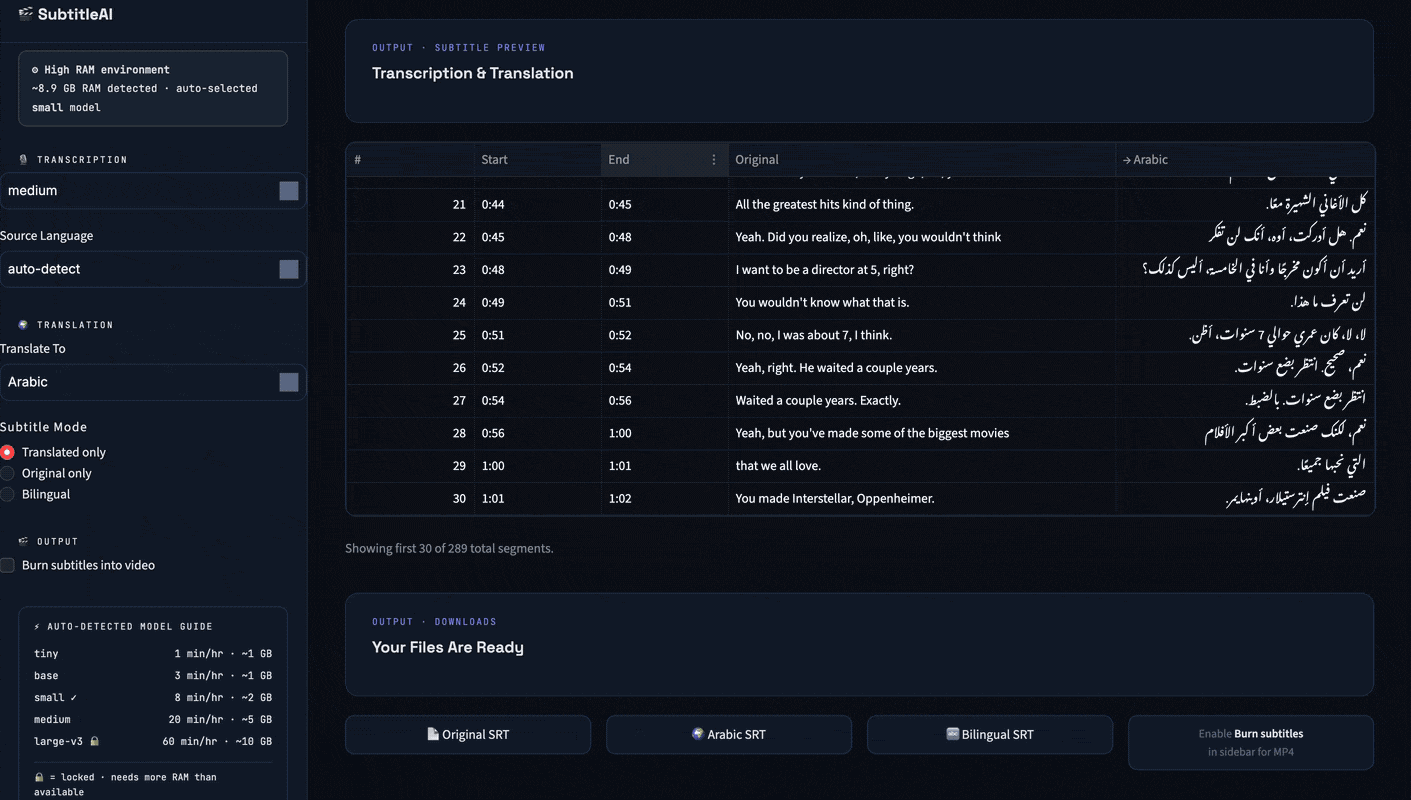
A full video localization pipeline. ffmpeg extracts audio, Whisper transcribes into timestamped segments, Llama-3.3-70B on Groq translates in batches of 25 across 20+ languages including Spanish, Arabic, and Italian. Outputs original, translated, or bilingual SRT, and can burn subtitles into an MP4. A live preview table shows original against translation before export.
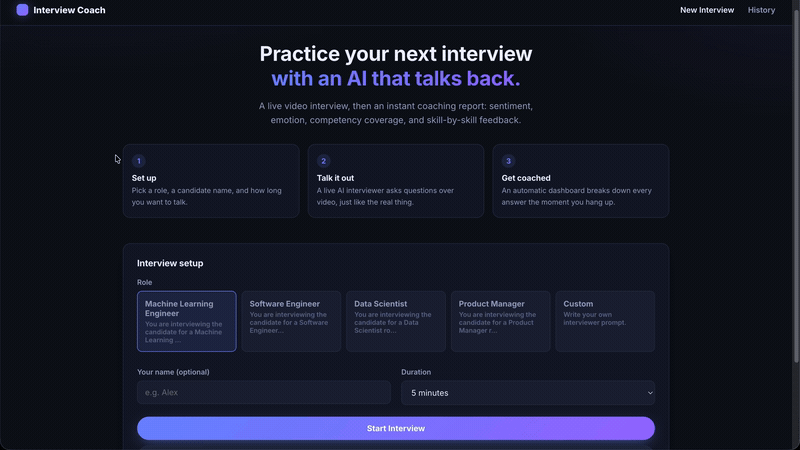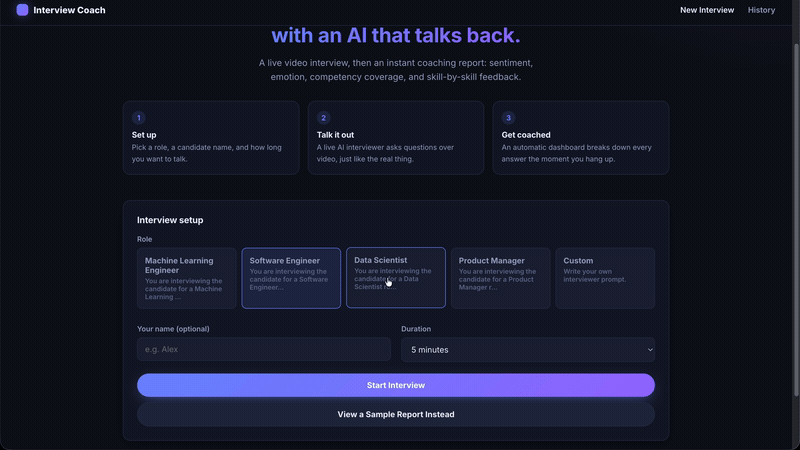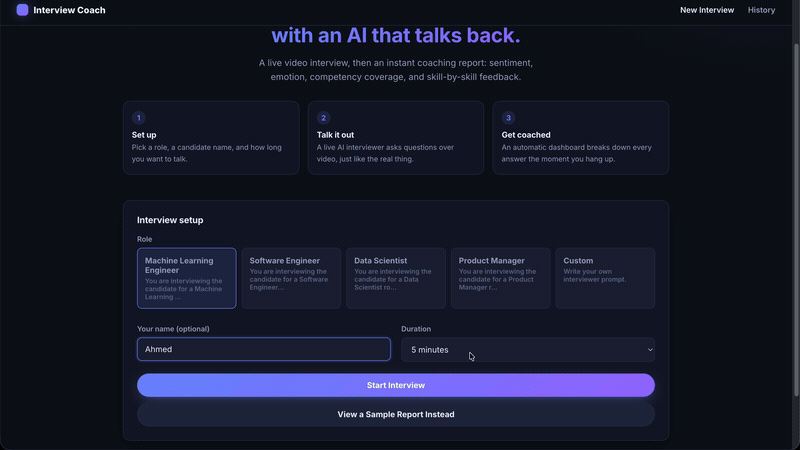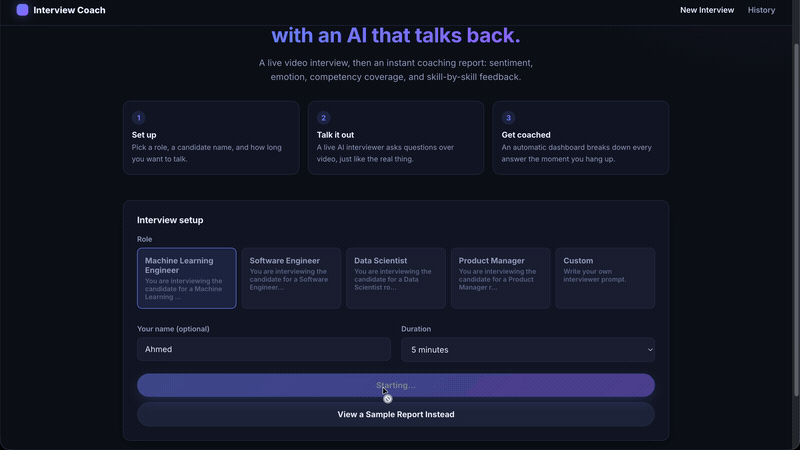
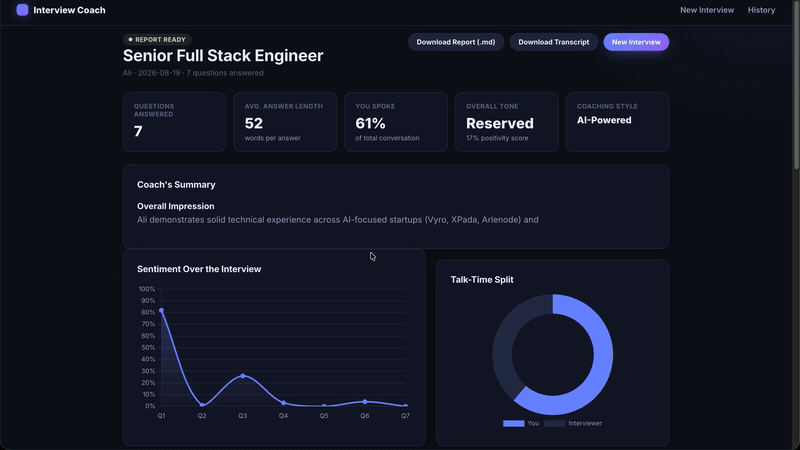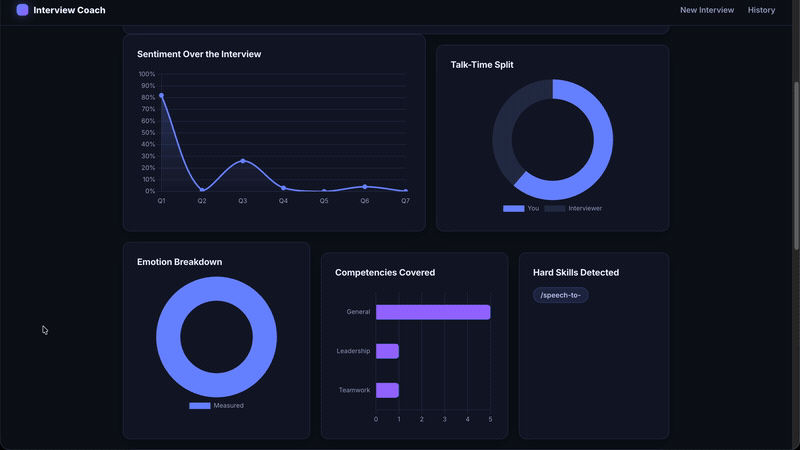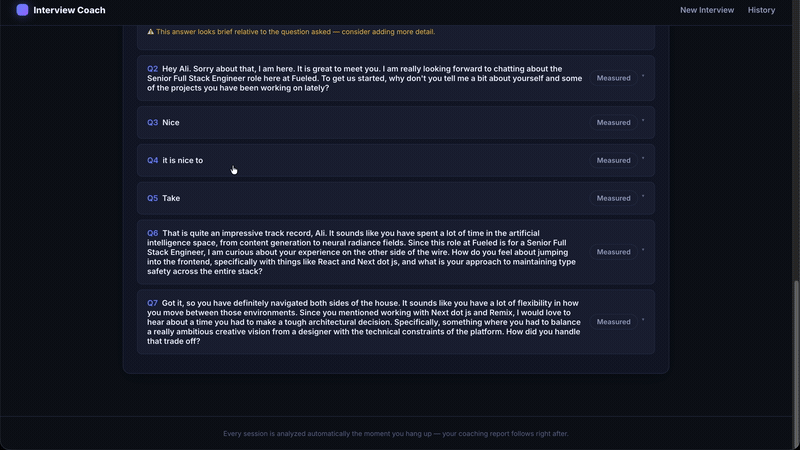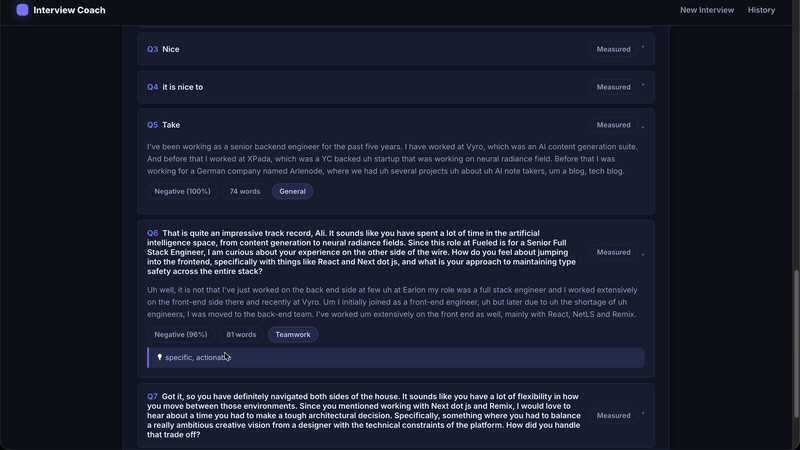
A live interview tool built on Tavus's Conversational Video Interface. Candidates talk to an AI interviewer over video; the moment the call ends, local HuggingFace models score sentiment and emotion per answer, competencies and hard skills get tagged, and an optional GPT layer writes per-question coaching notes — all rendered into an in-browser dashboard.
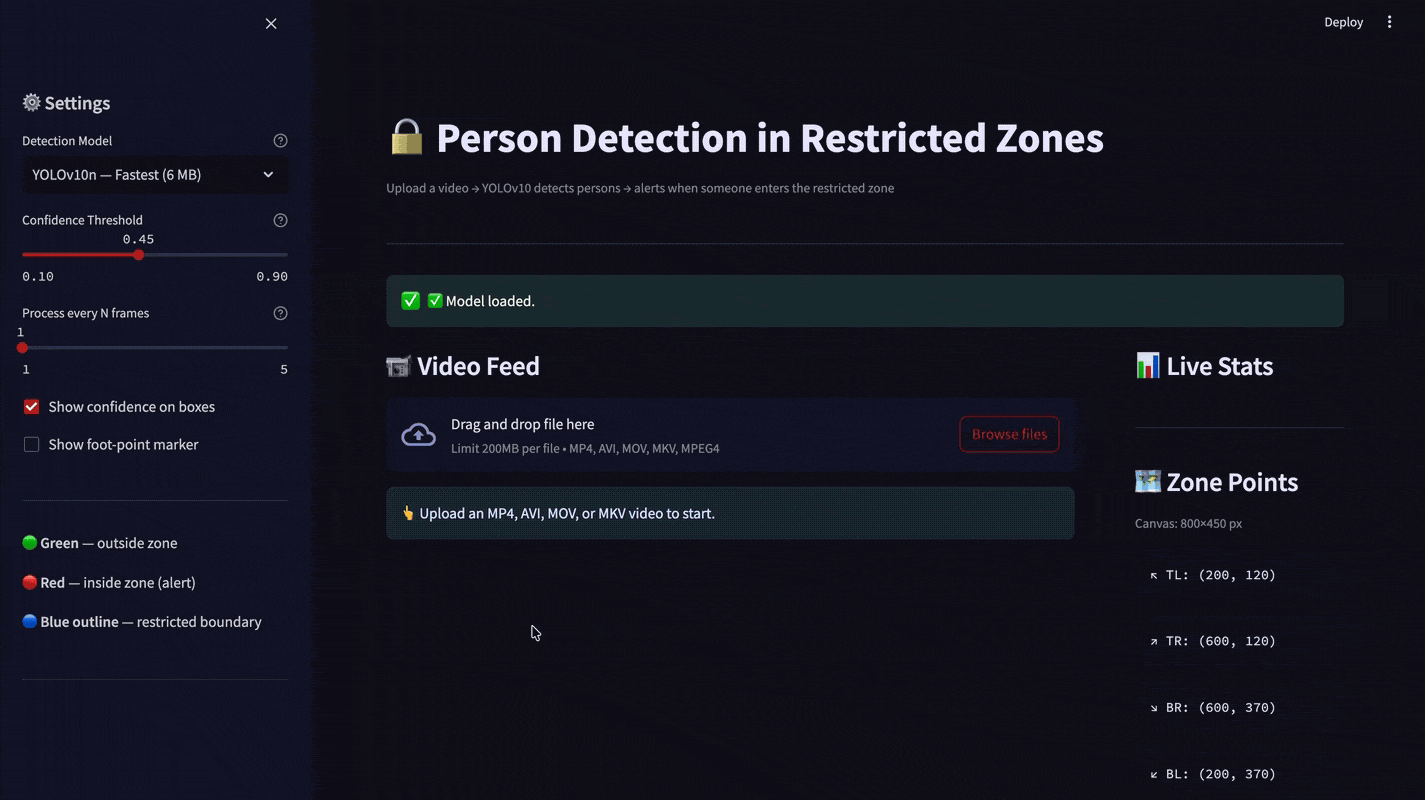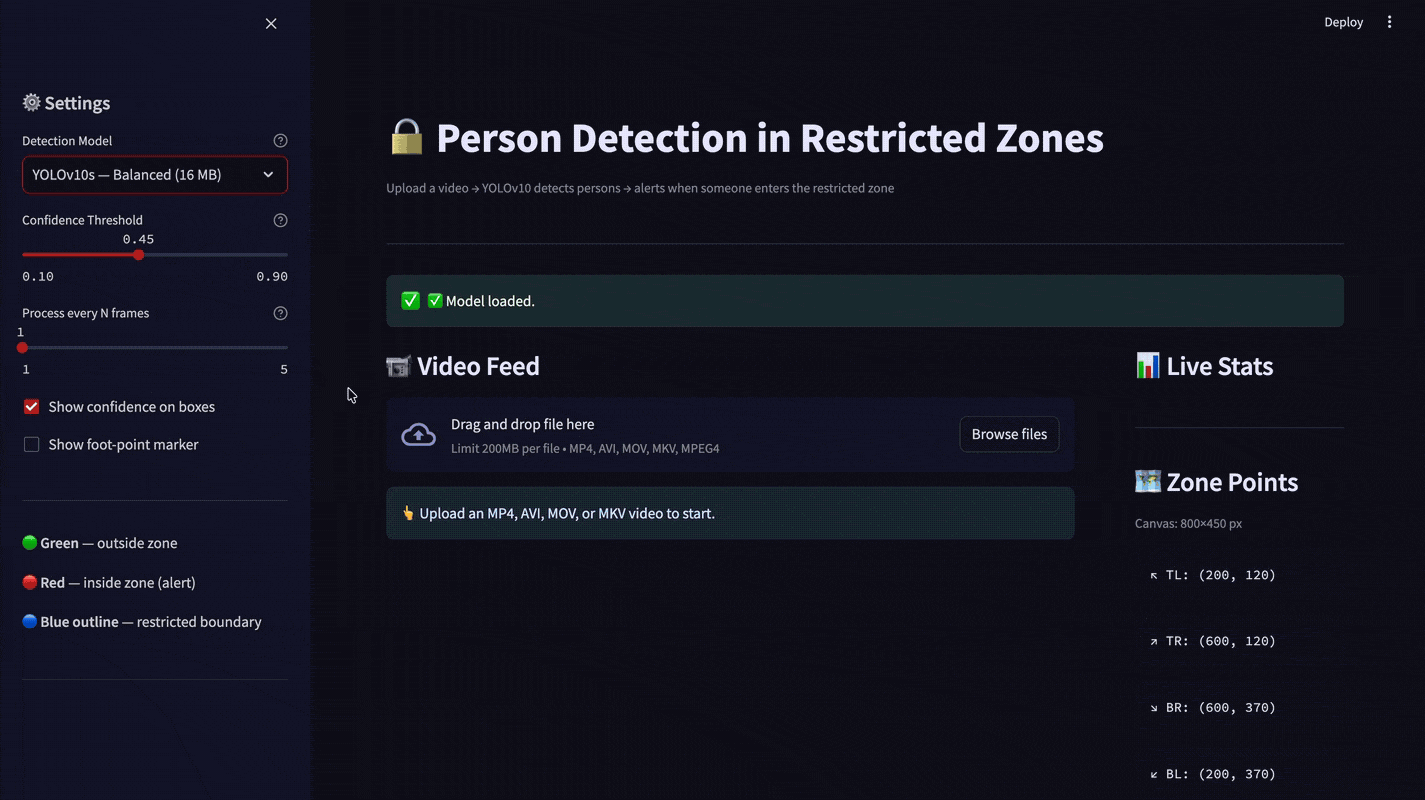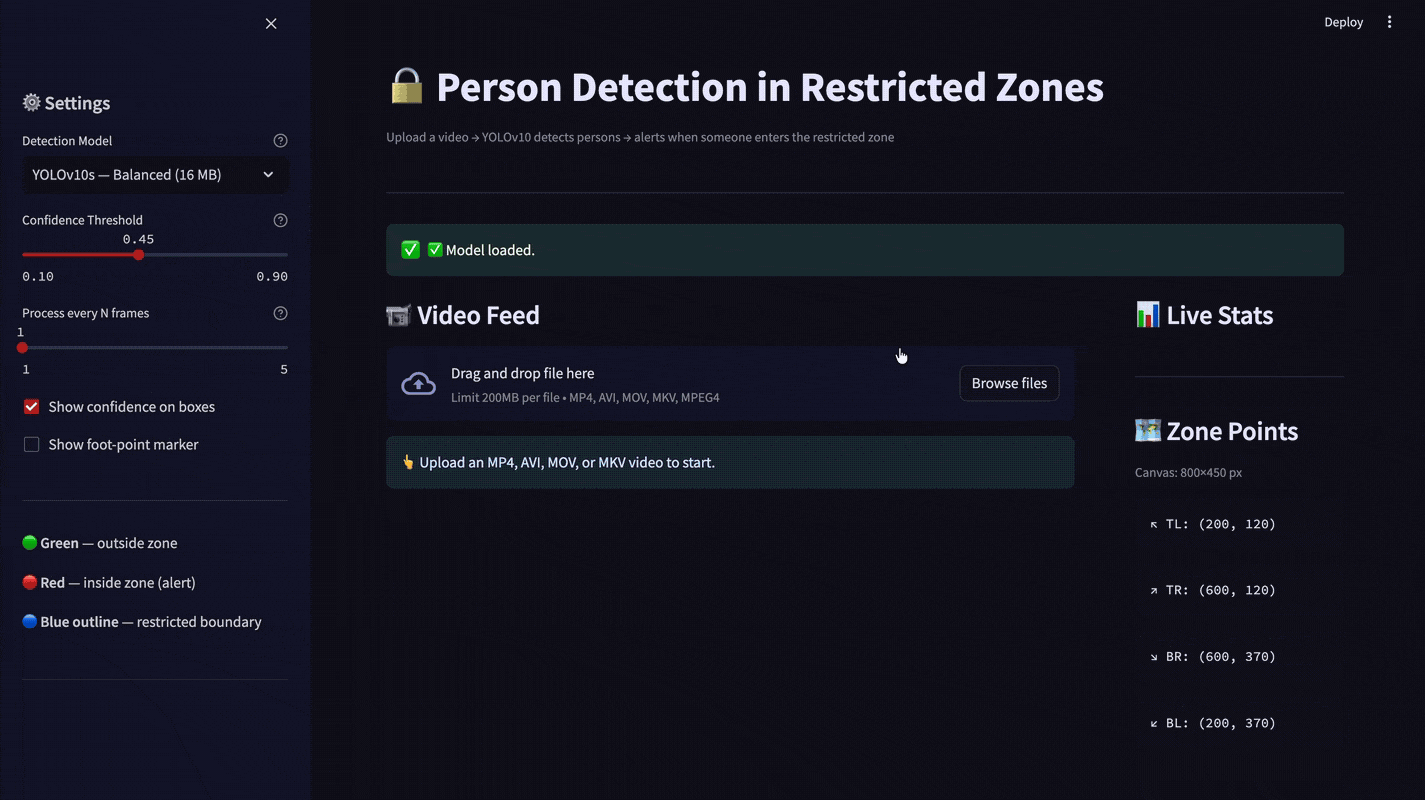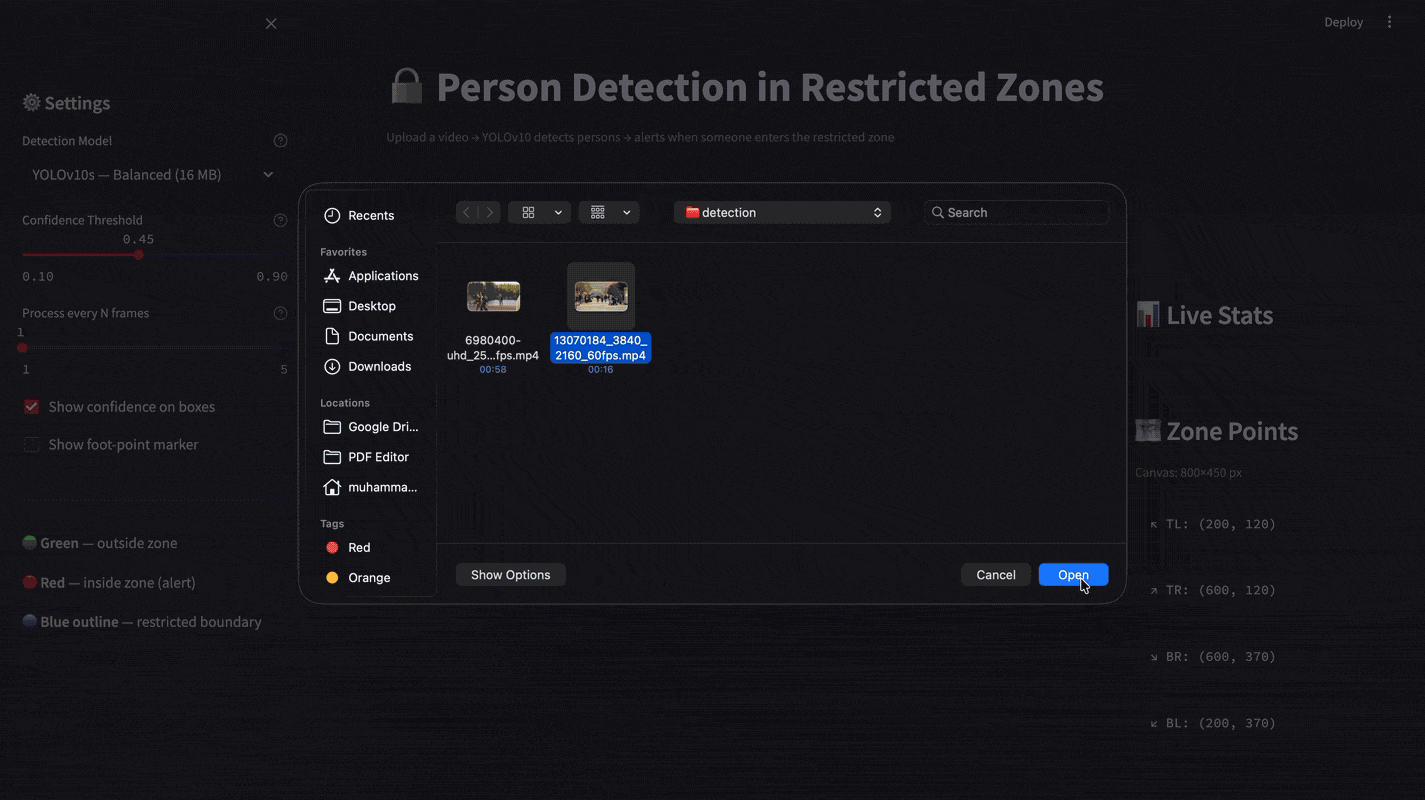
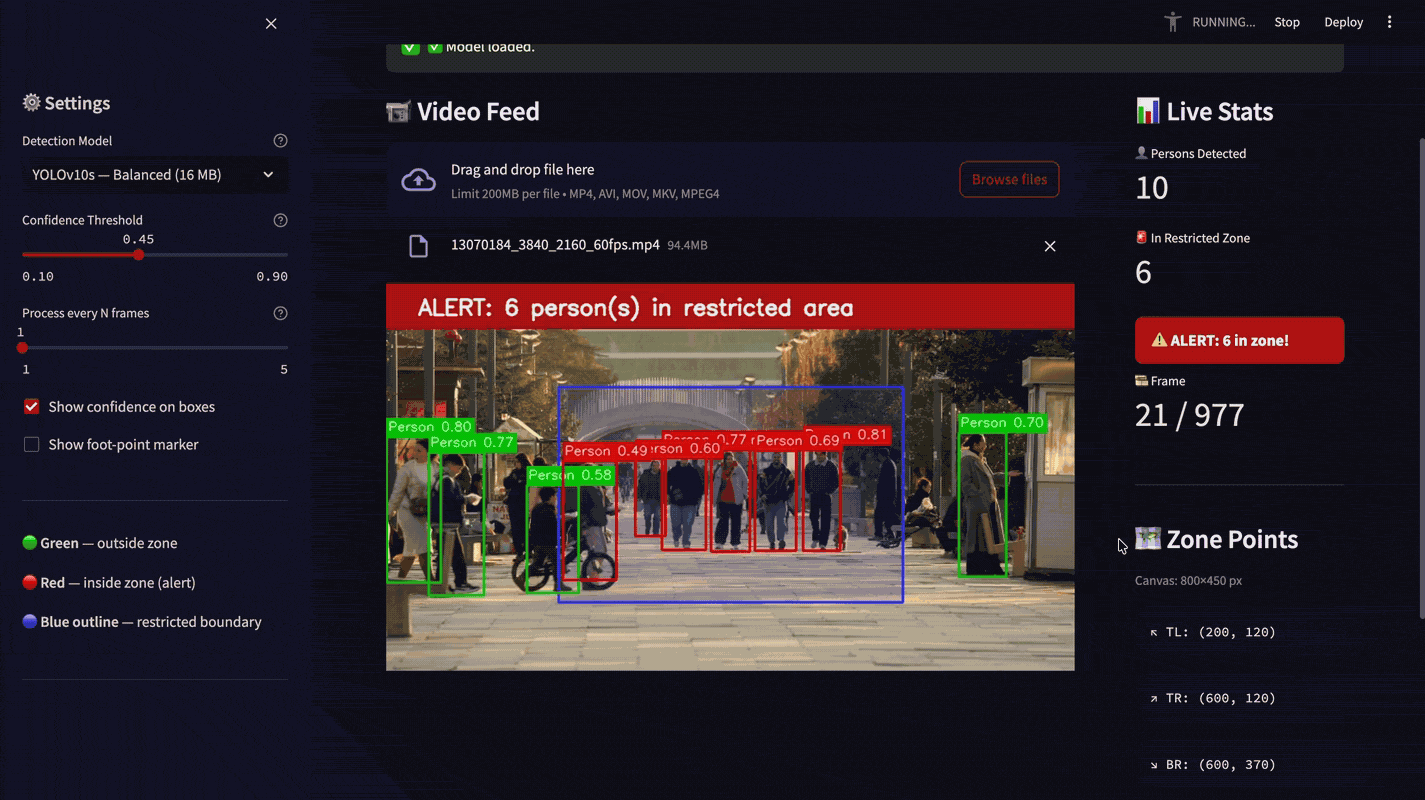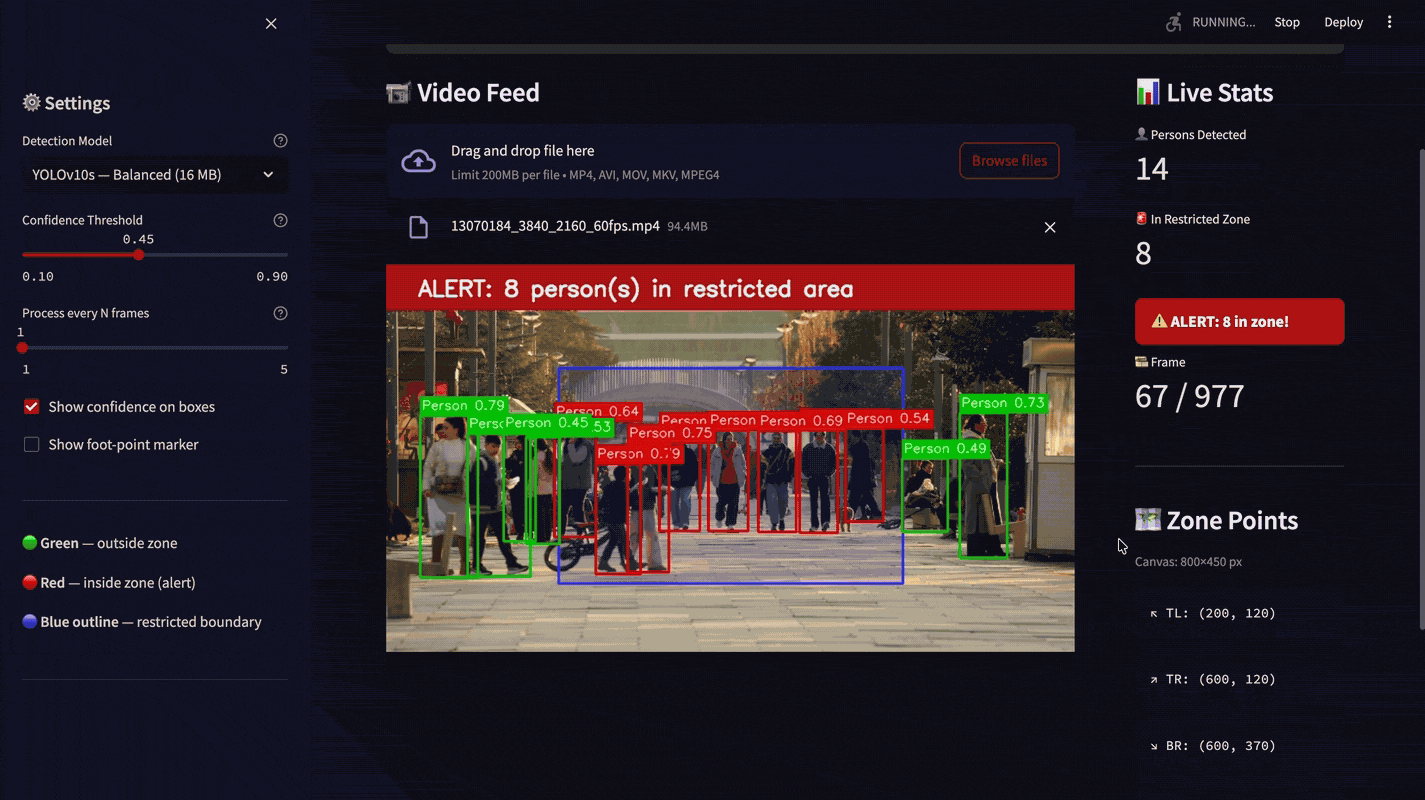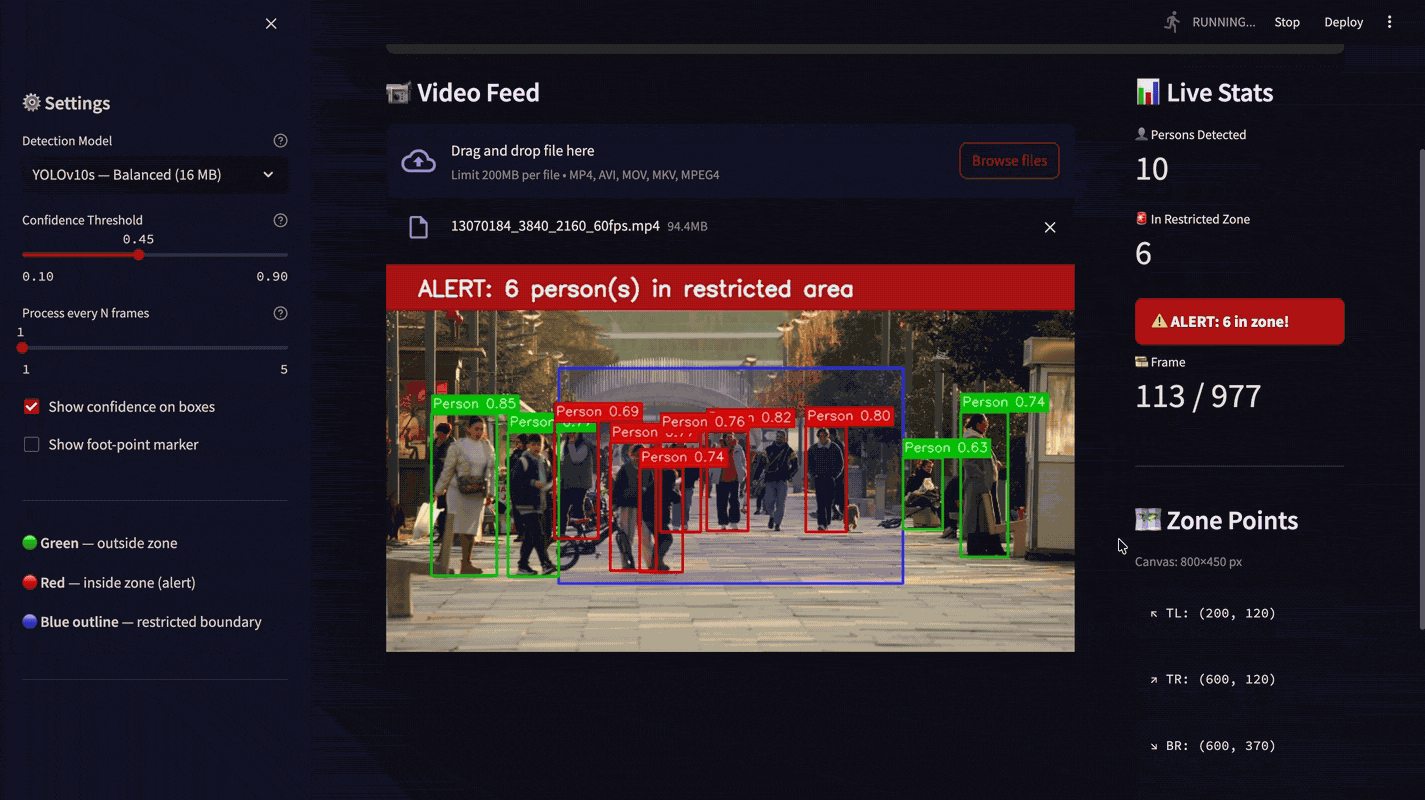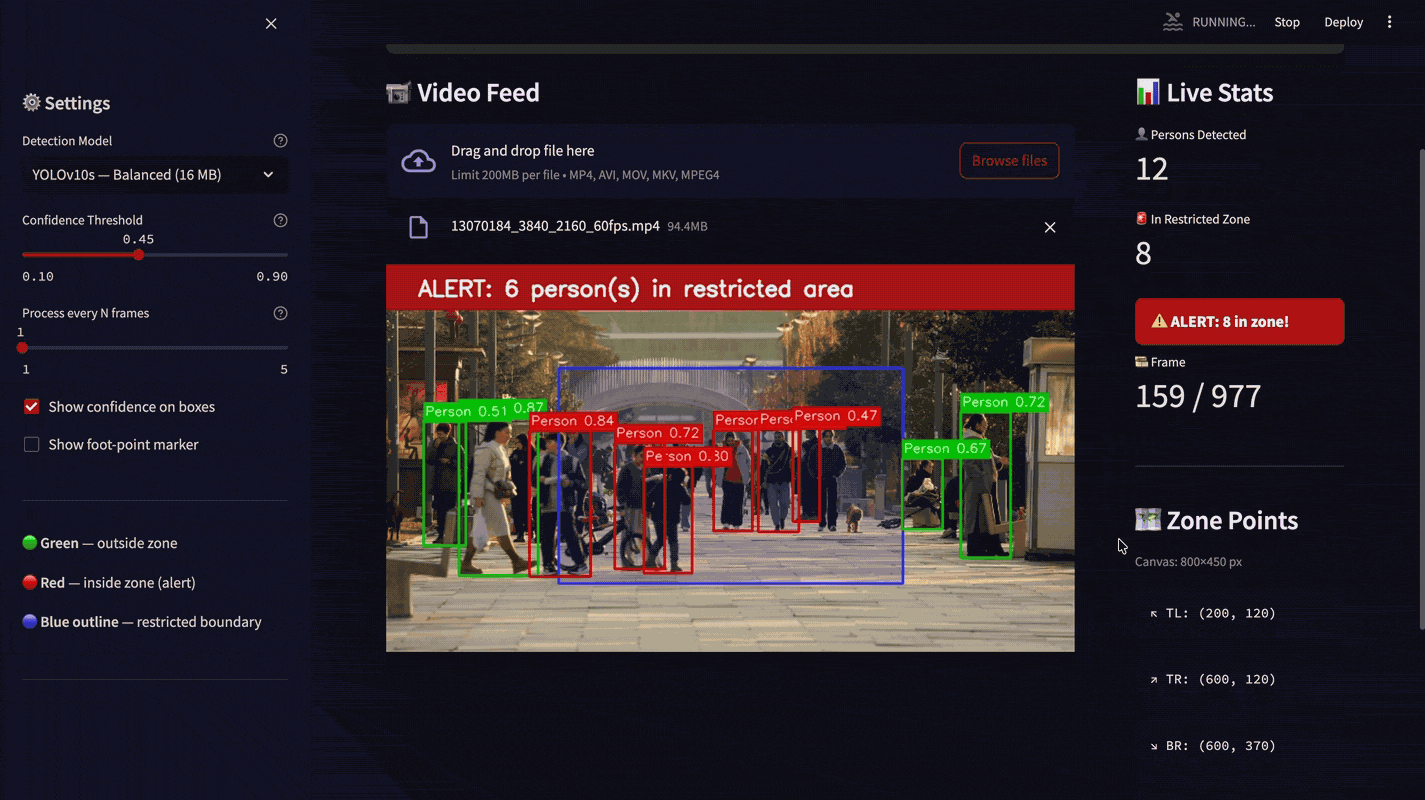
Surveillance-style intrusion detection on YOLOv10. Every detected person is tracked against a configurable polygon zone — arbitrary shape, not a fixed rectangle. Outside: green box. Inside: red box and an alert banner at the moment of crossing. Zone geometry, confidence threshold, and frame rate are adjustable at runtime, so the same code runs a demo clip or a live camera feed.
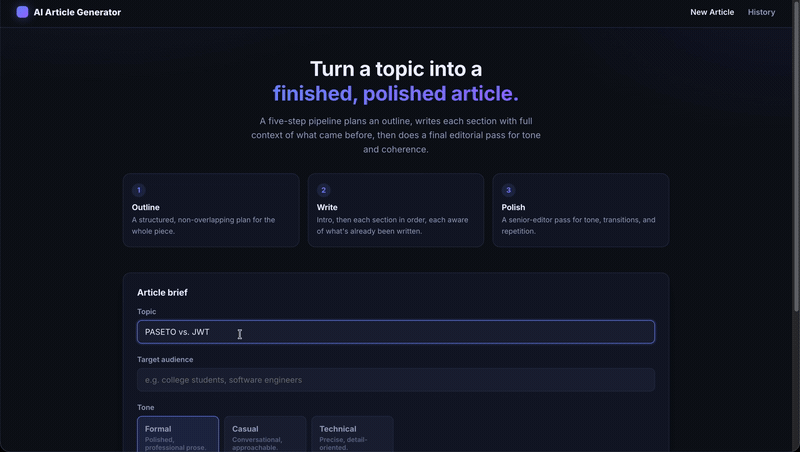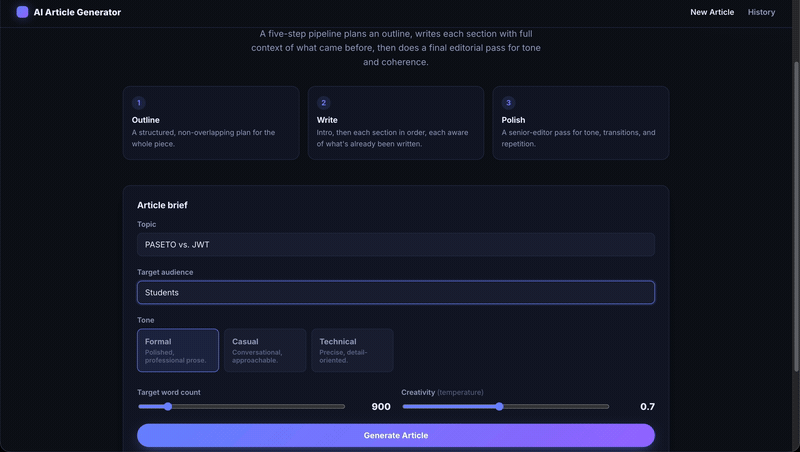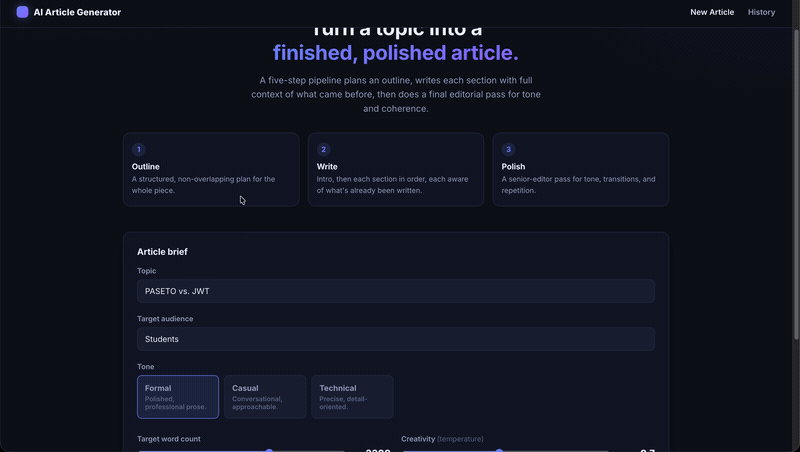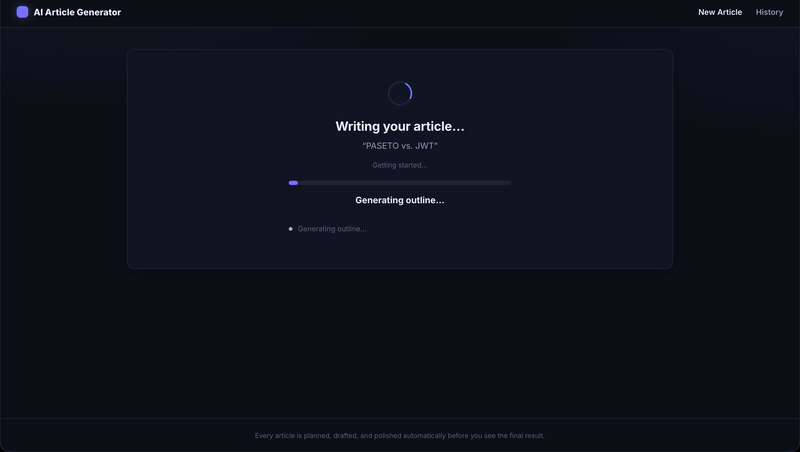
A 5-step LangChain pipeline — outline, intro, sections, conclusion, polish — that plans an article's structure before writing a word of it, streaming real per-step progress instead of a spinner. Exports to a properly formatted .docx via a real markdown-it-py parse-tree walk, so headings, tables, and hyperlinks all round-trip correctly into Word.
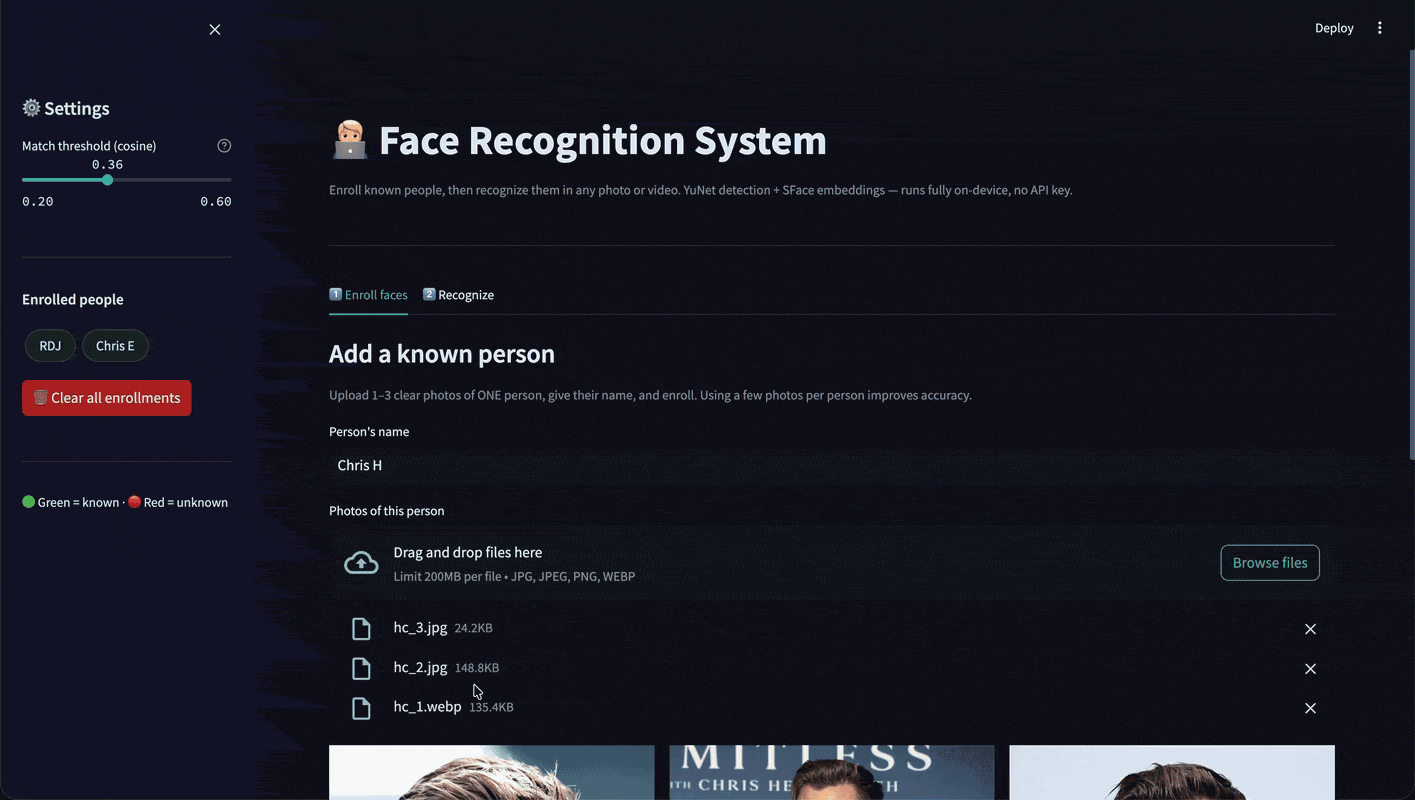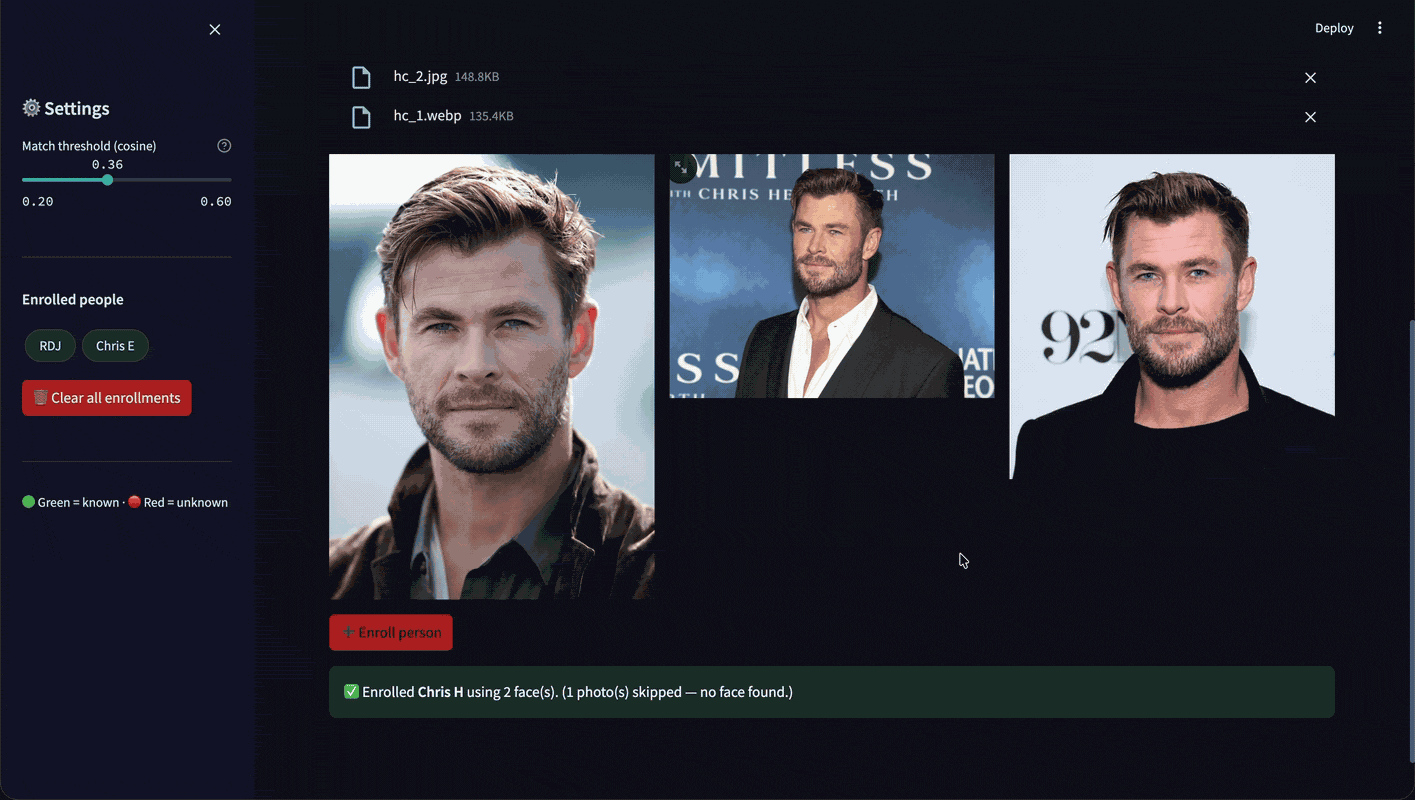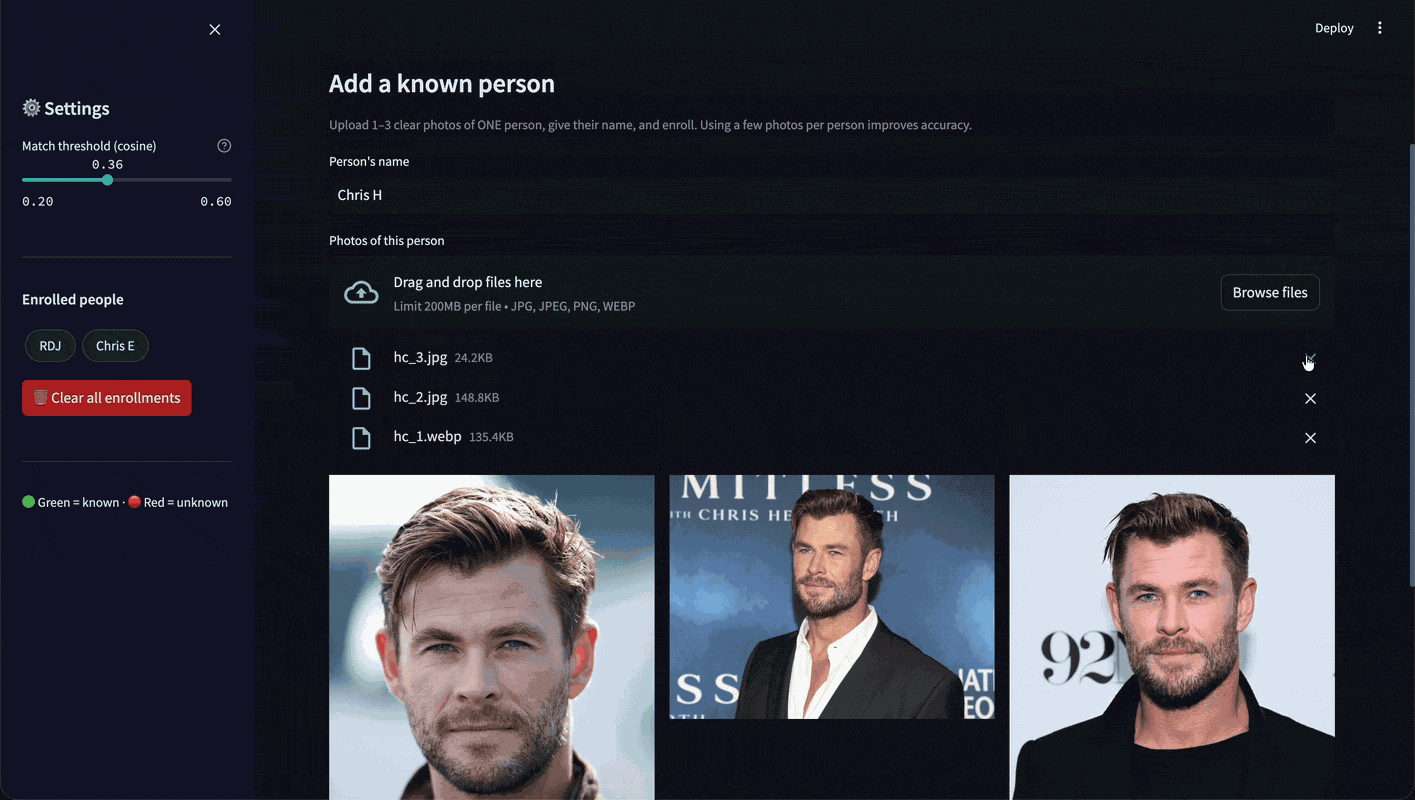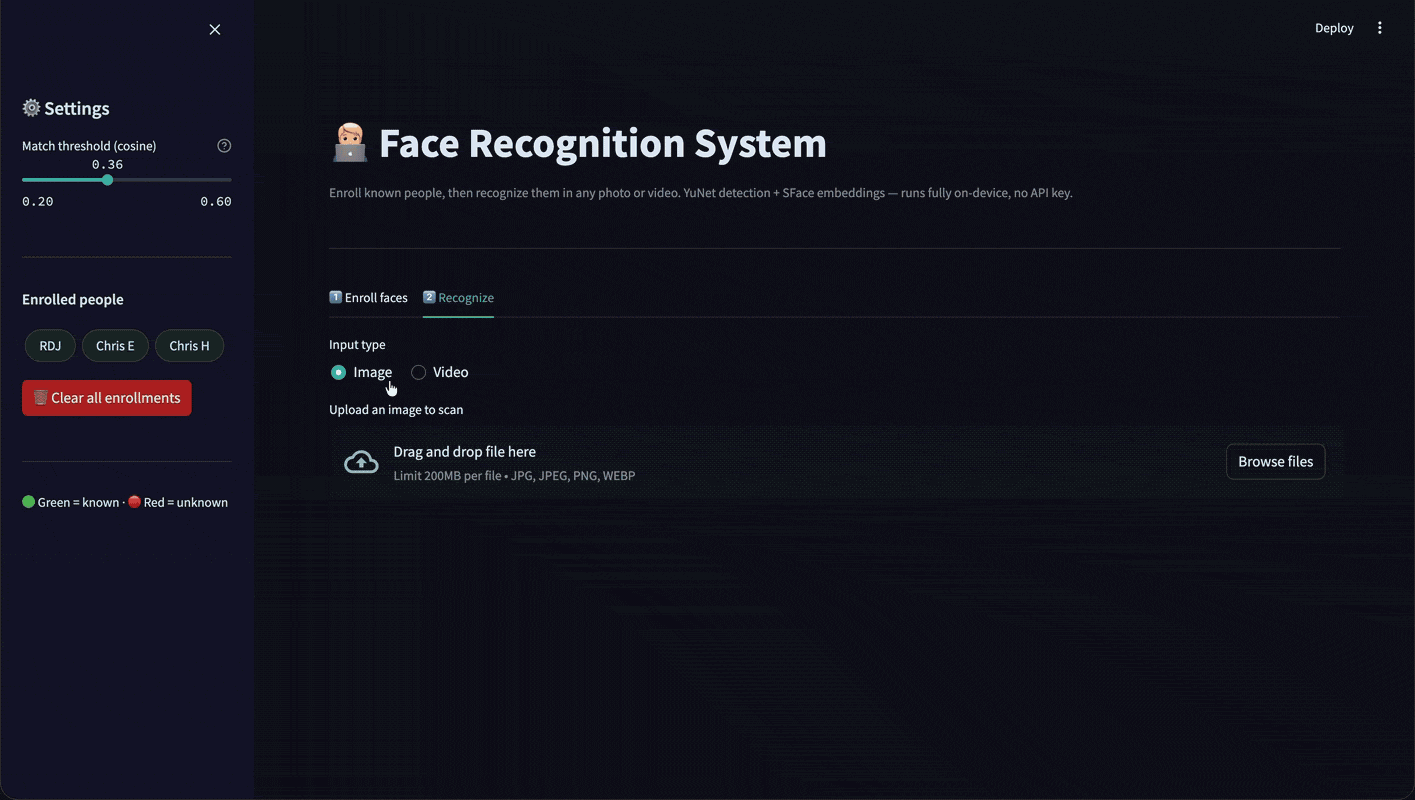
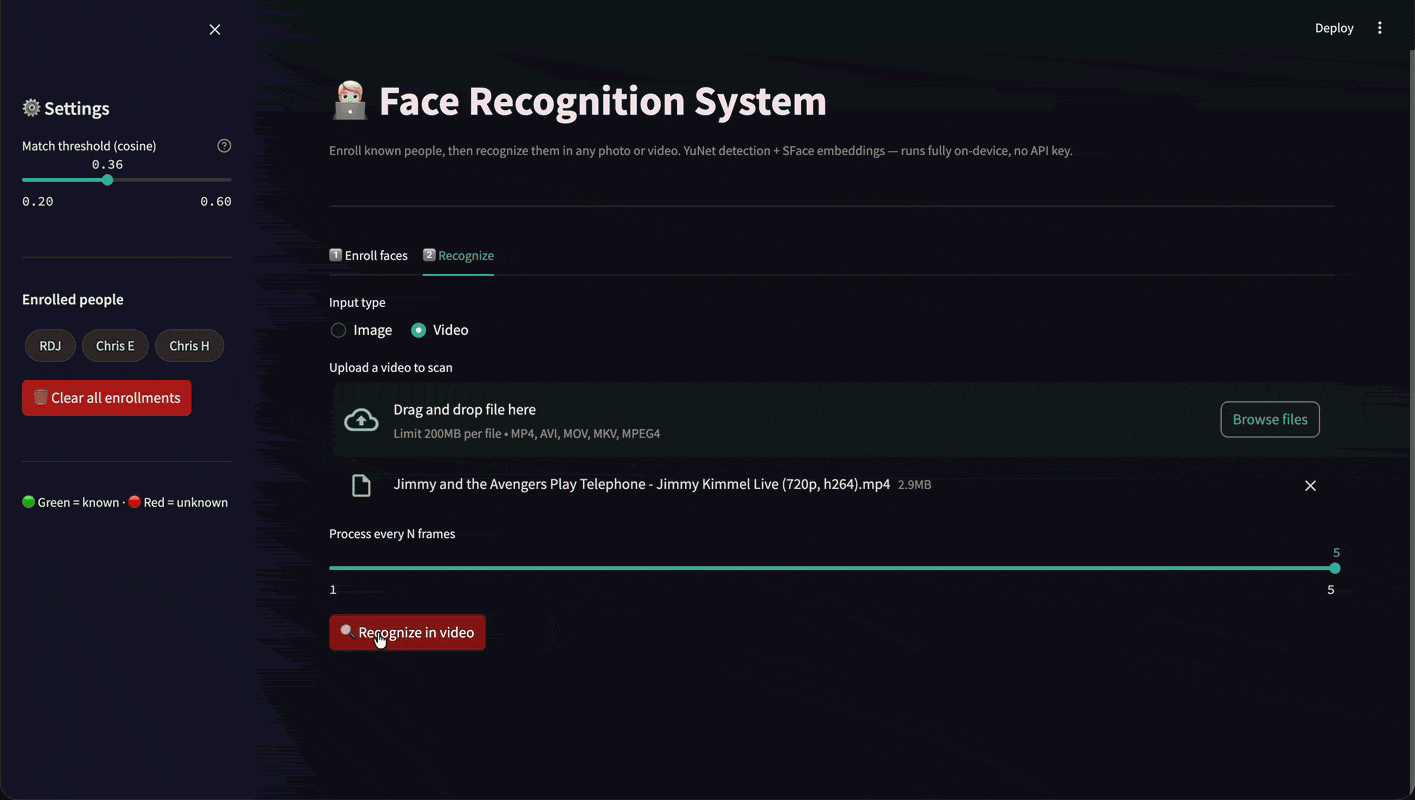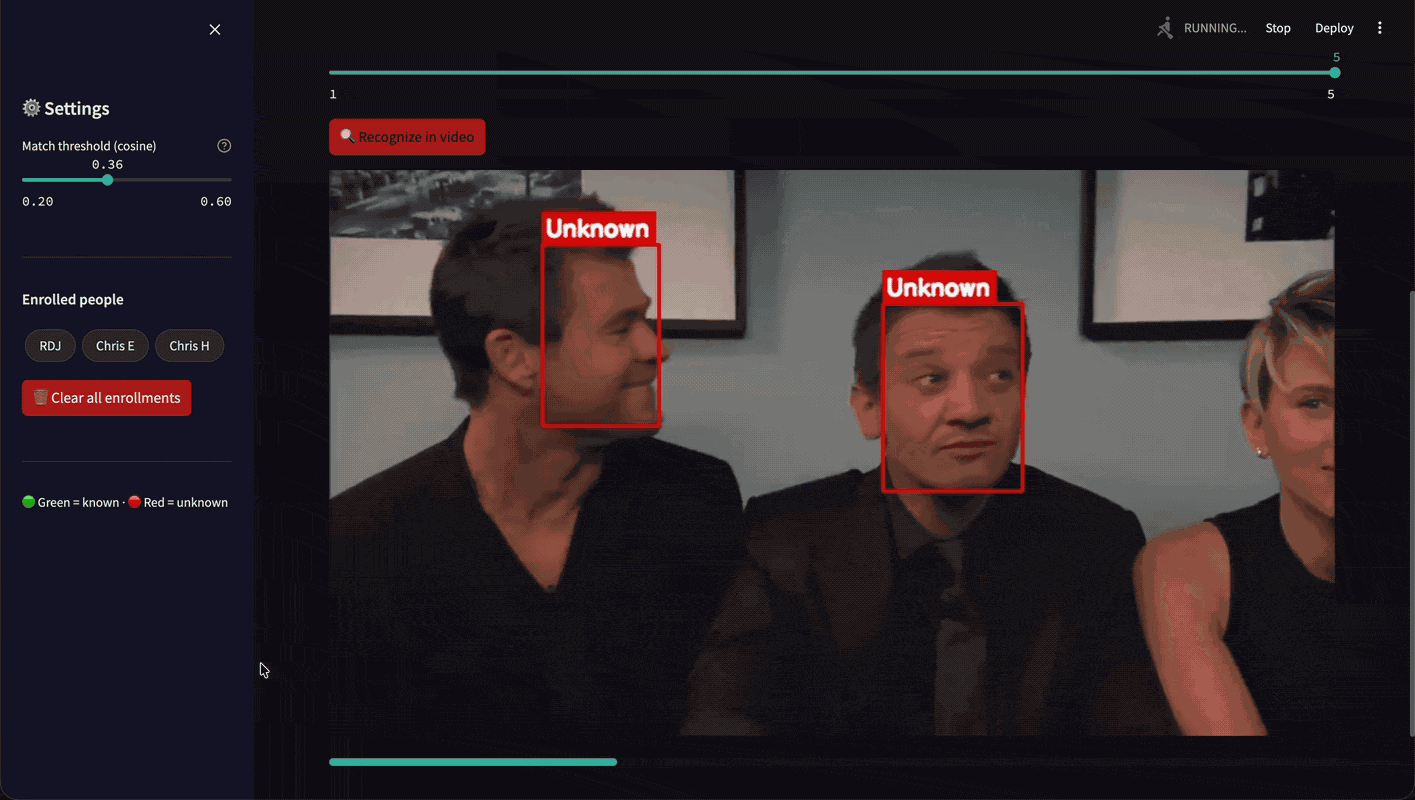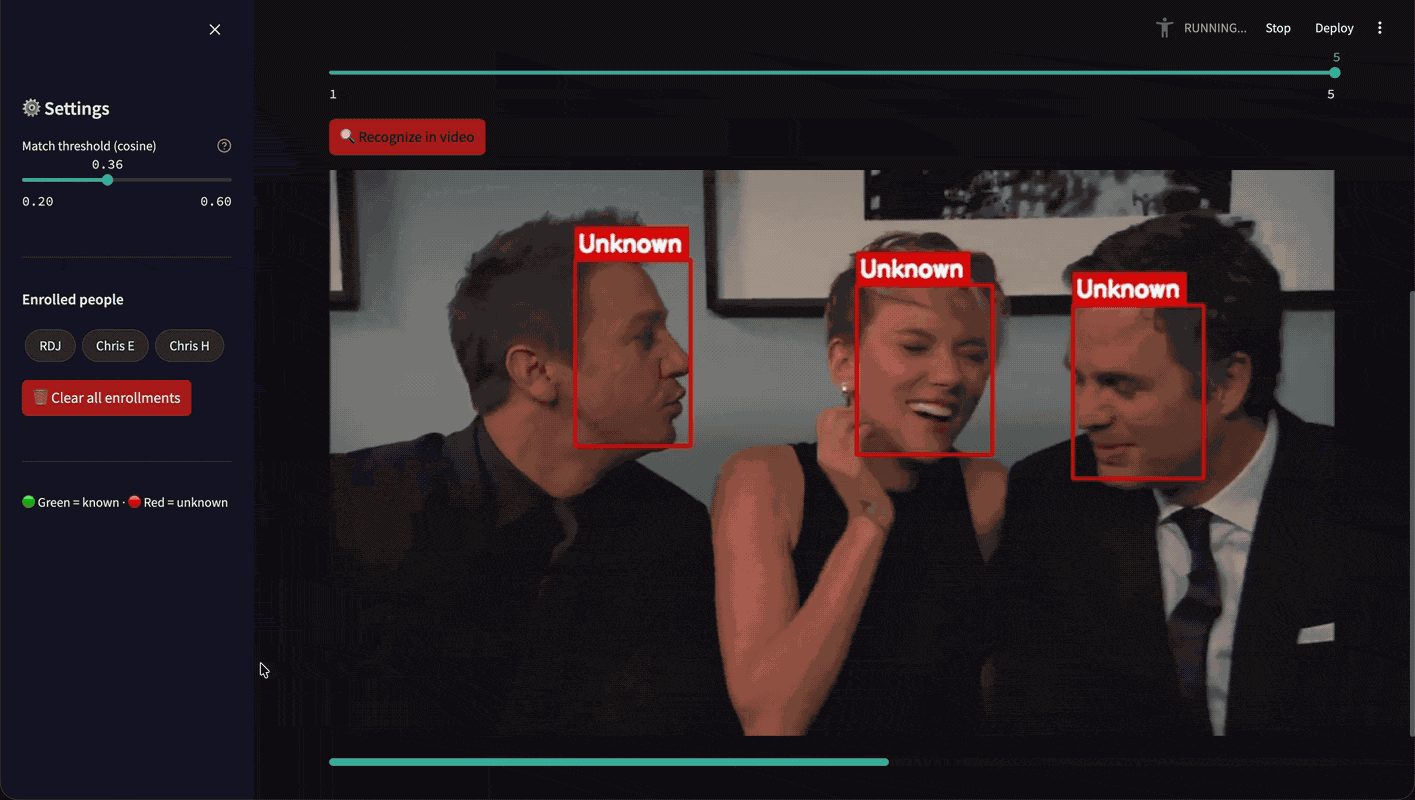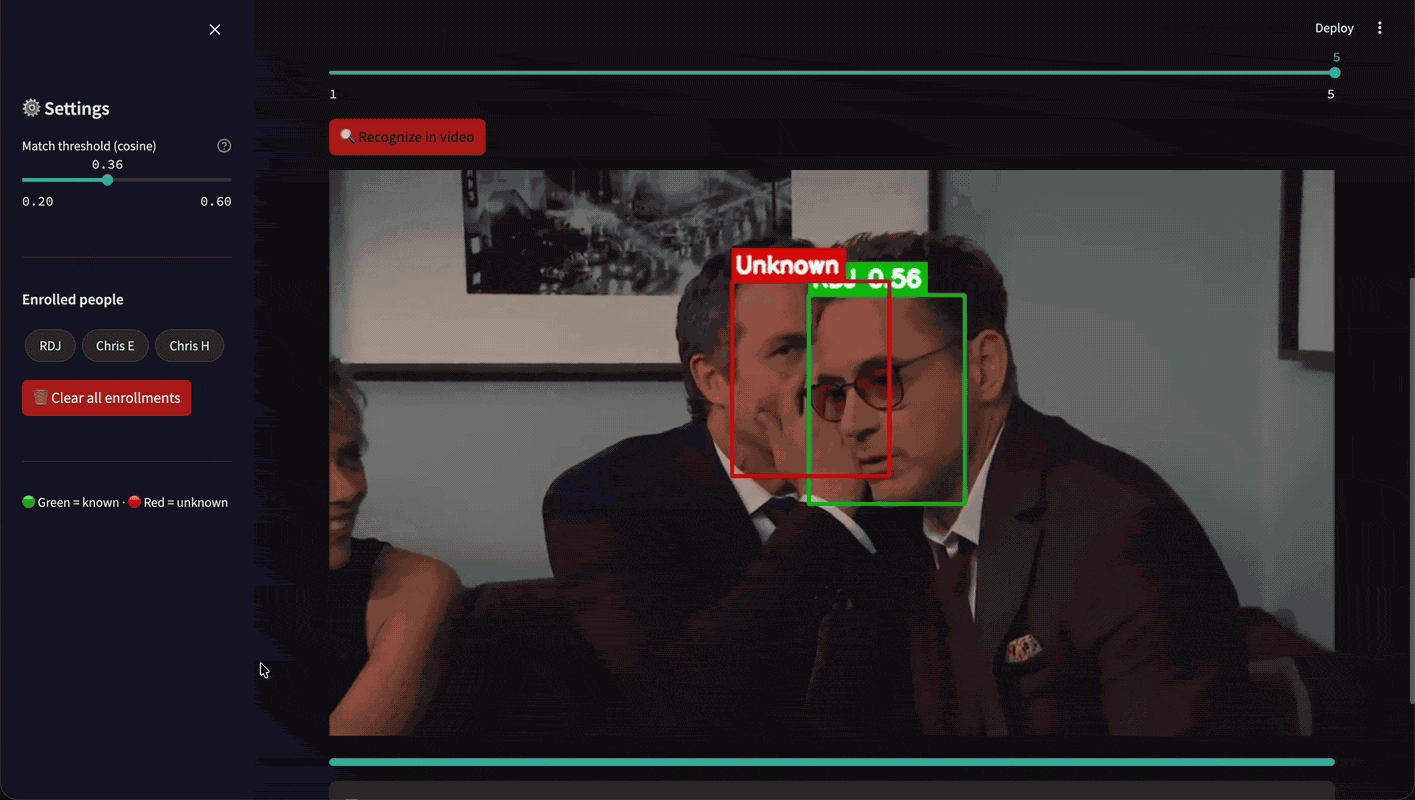
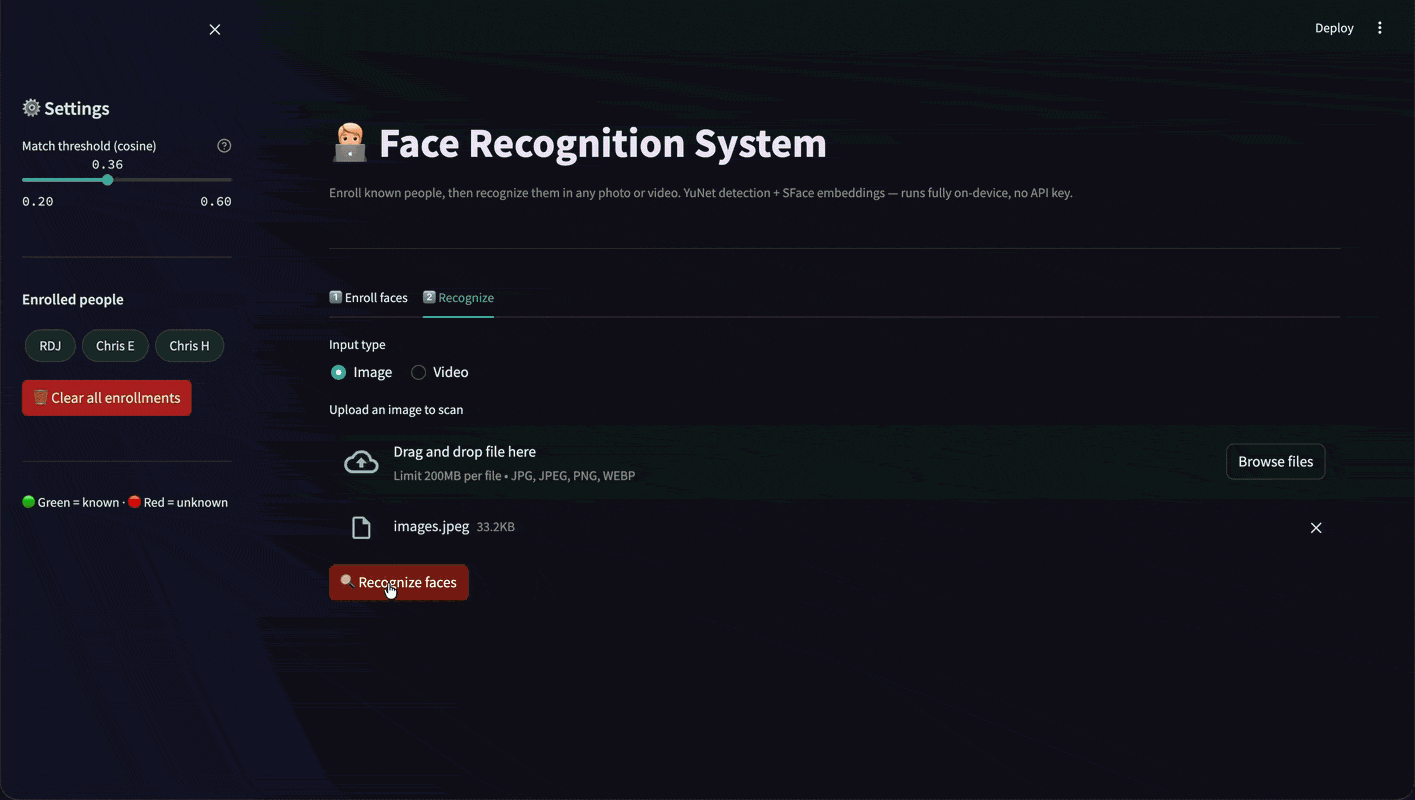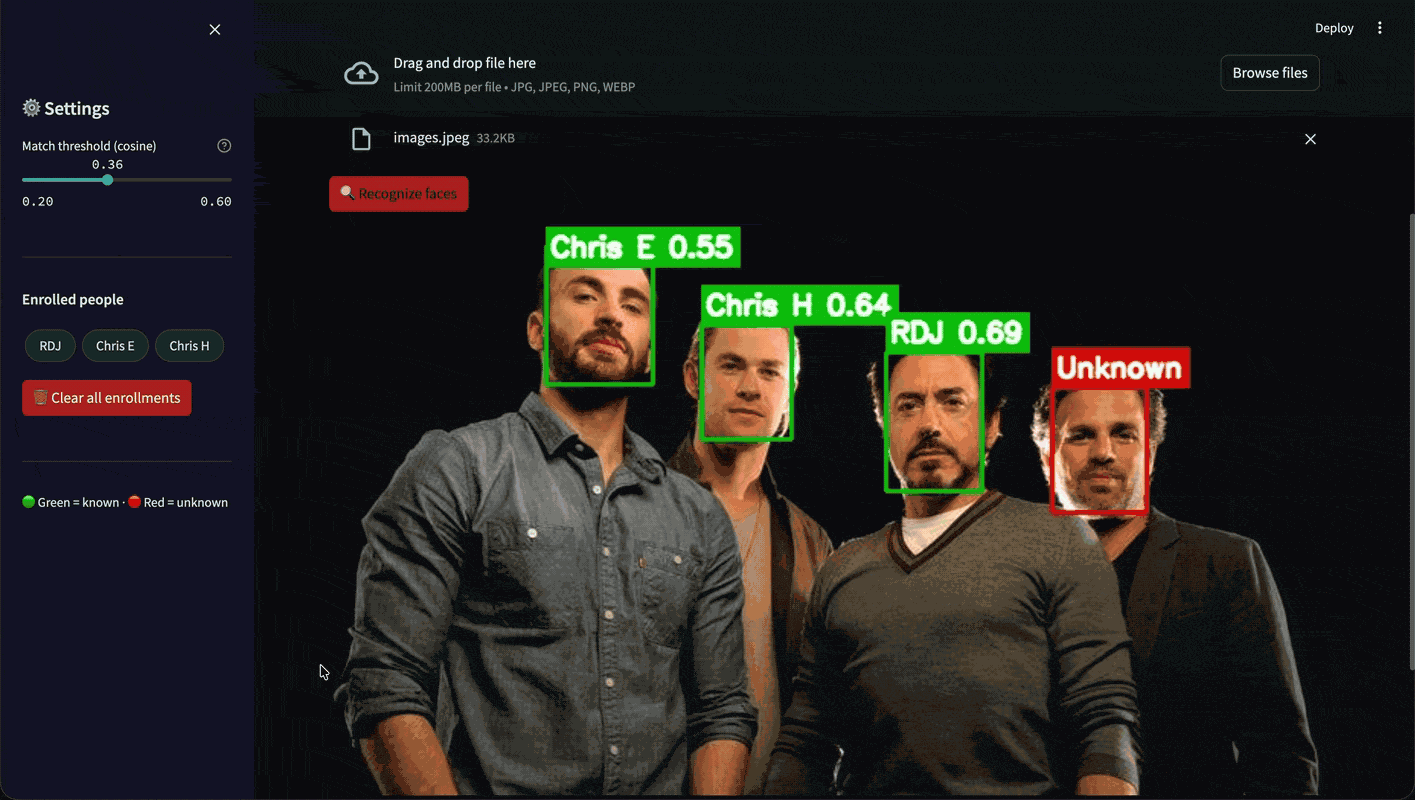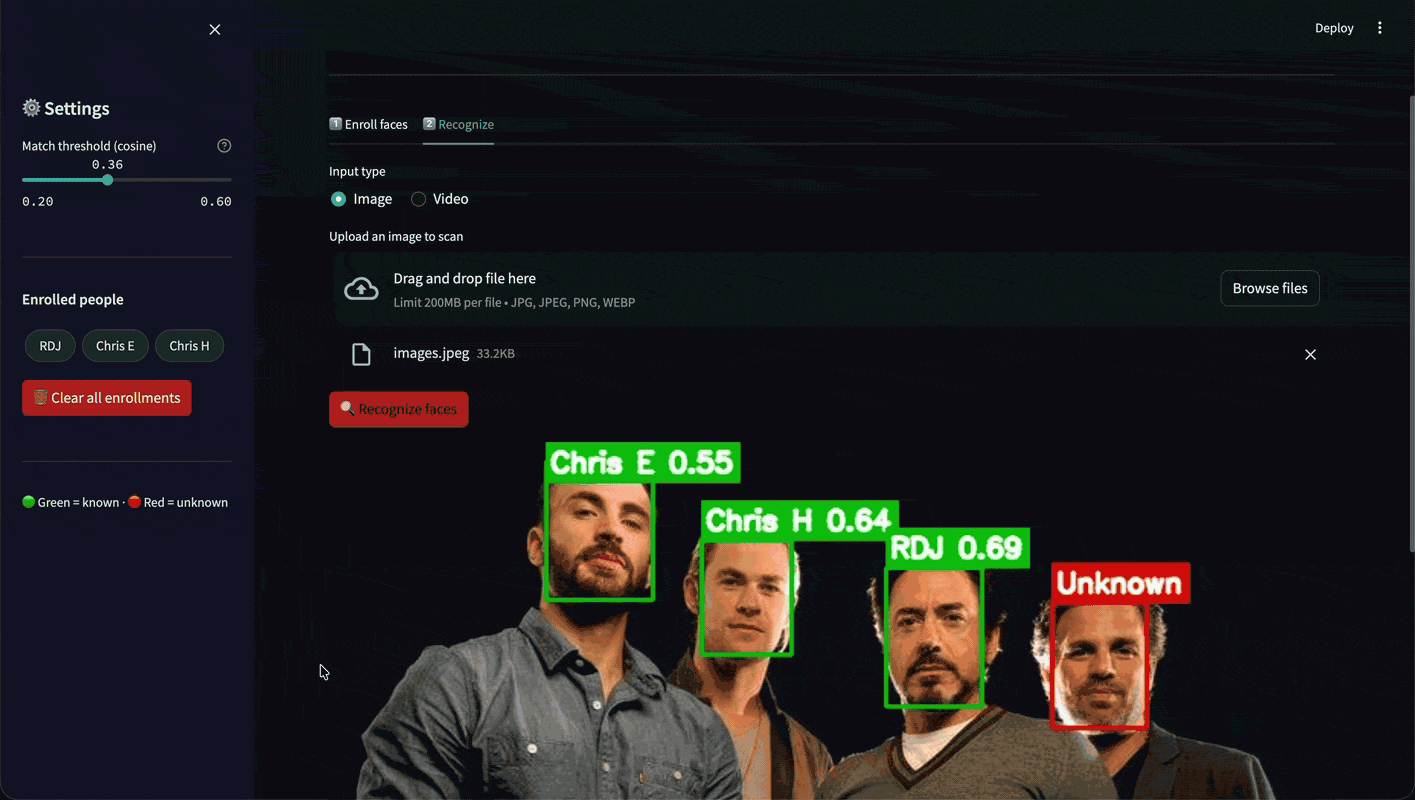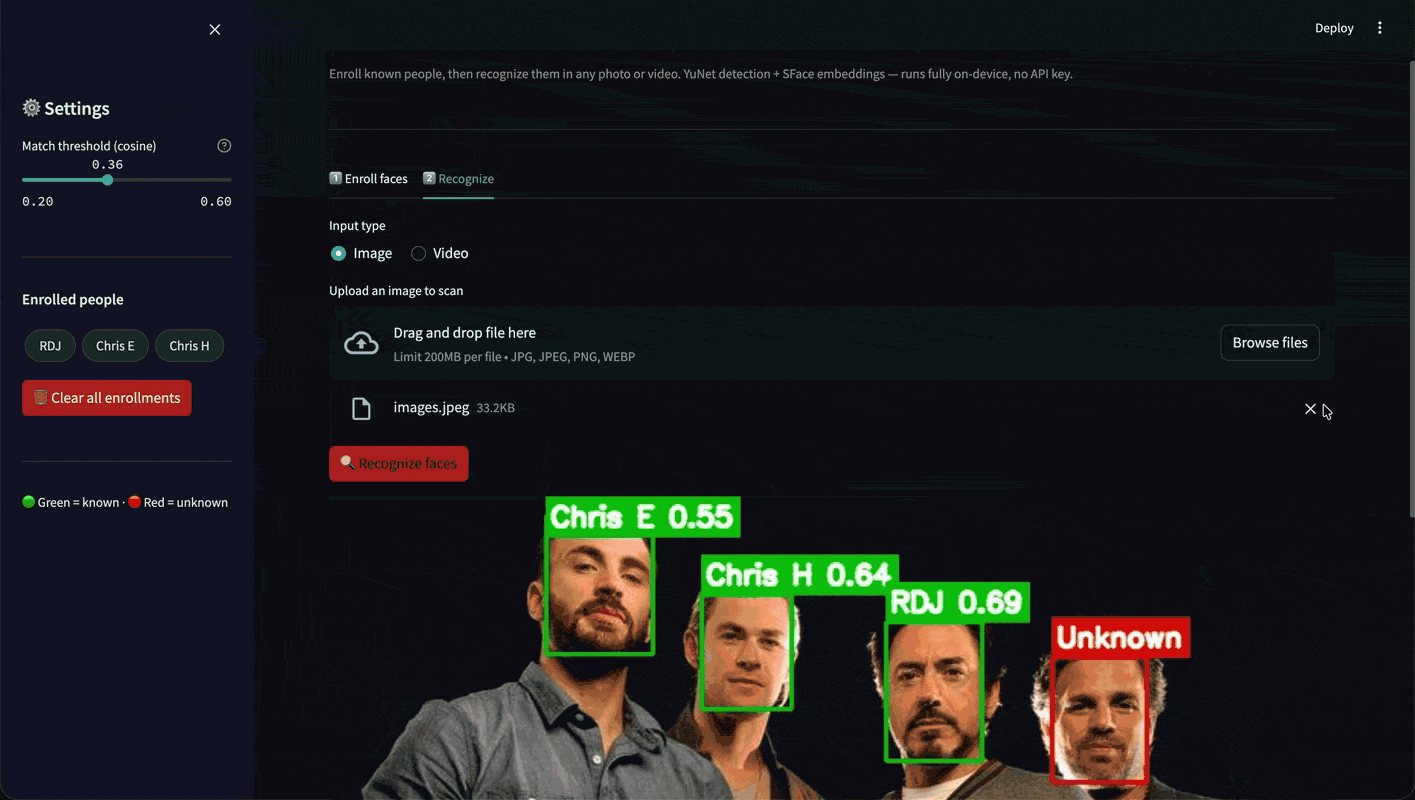
Built deliberately without dlib — the dependency that routinely breaks cloud builds via C++ compilation failures. Instead: OpenCV's YuNet for detection, SFace for 128-d embeddings. Two ONNX files, ~5MB, CPU-only, deploys clean. Enroll from 1–3 photos; matching is cosine similarity against SFace's 0.363 threshold.
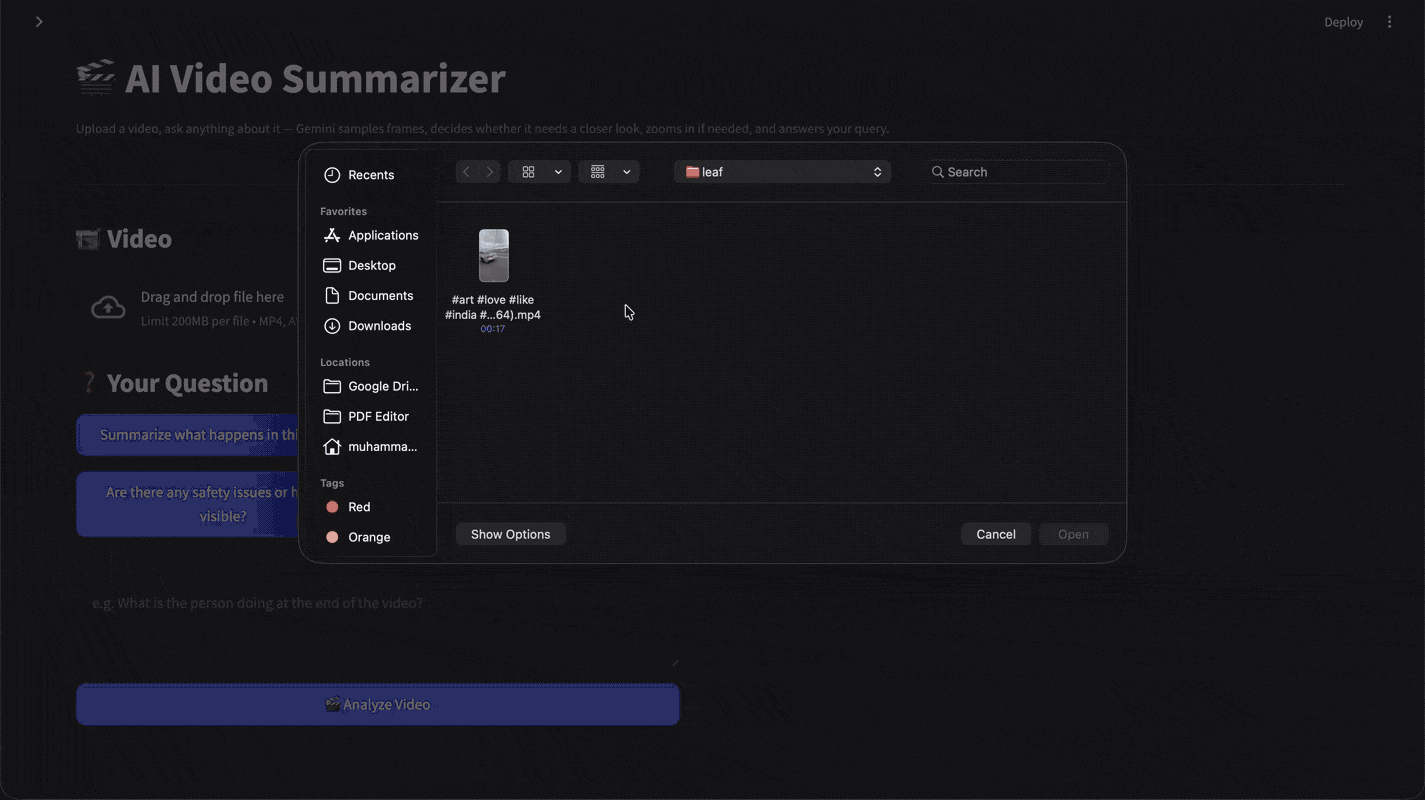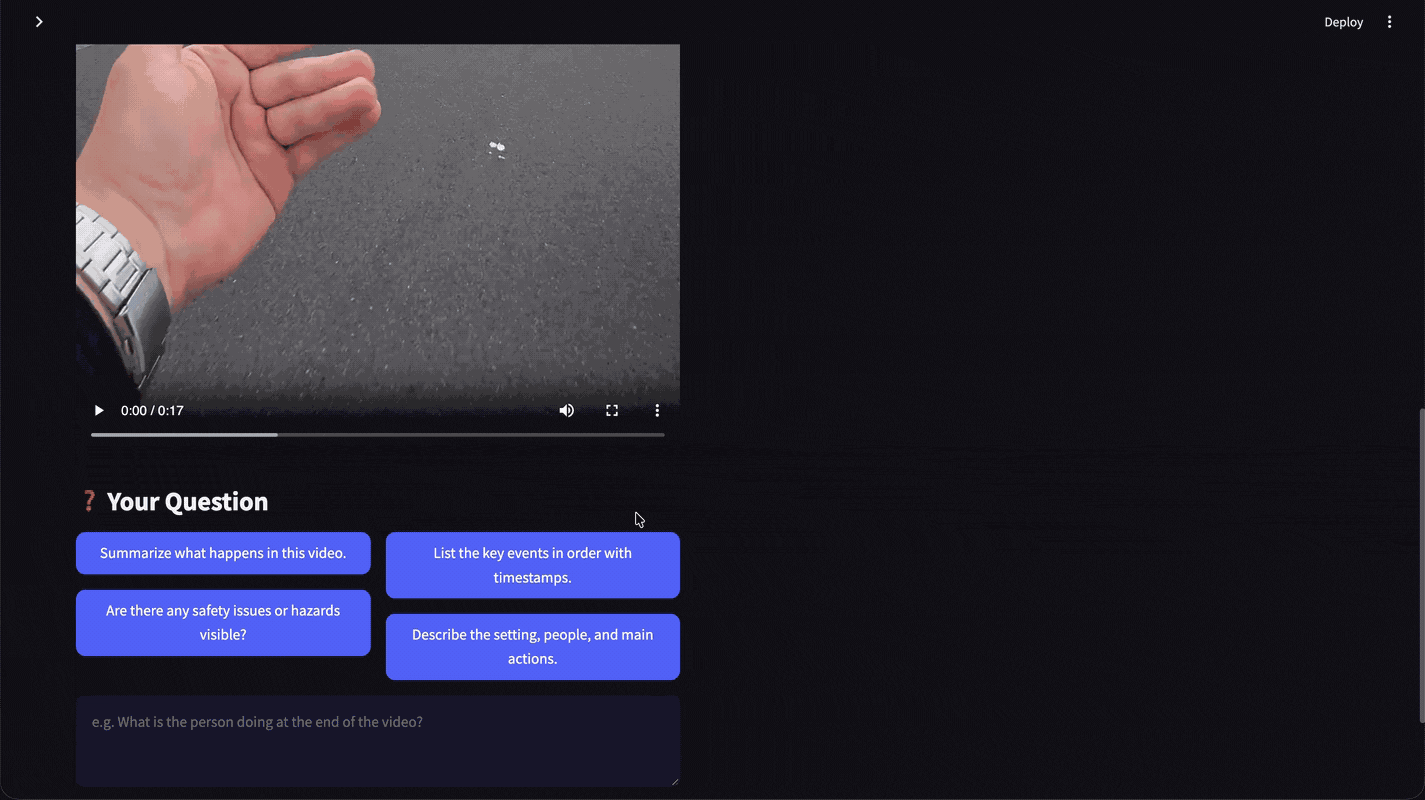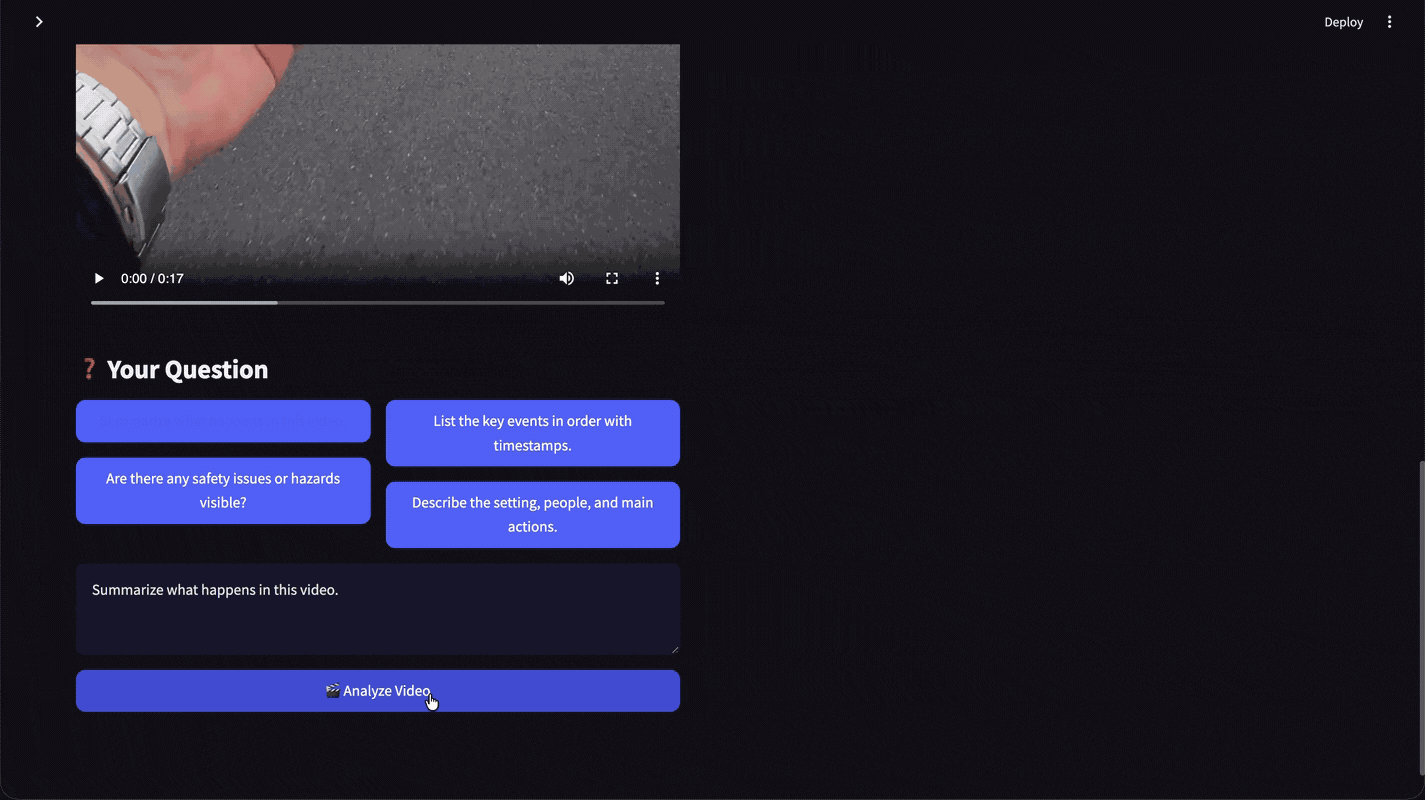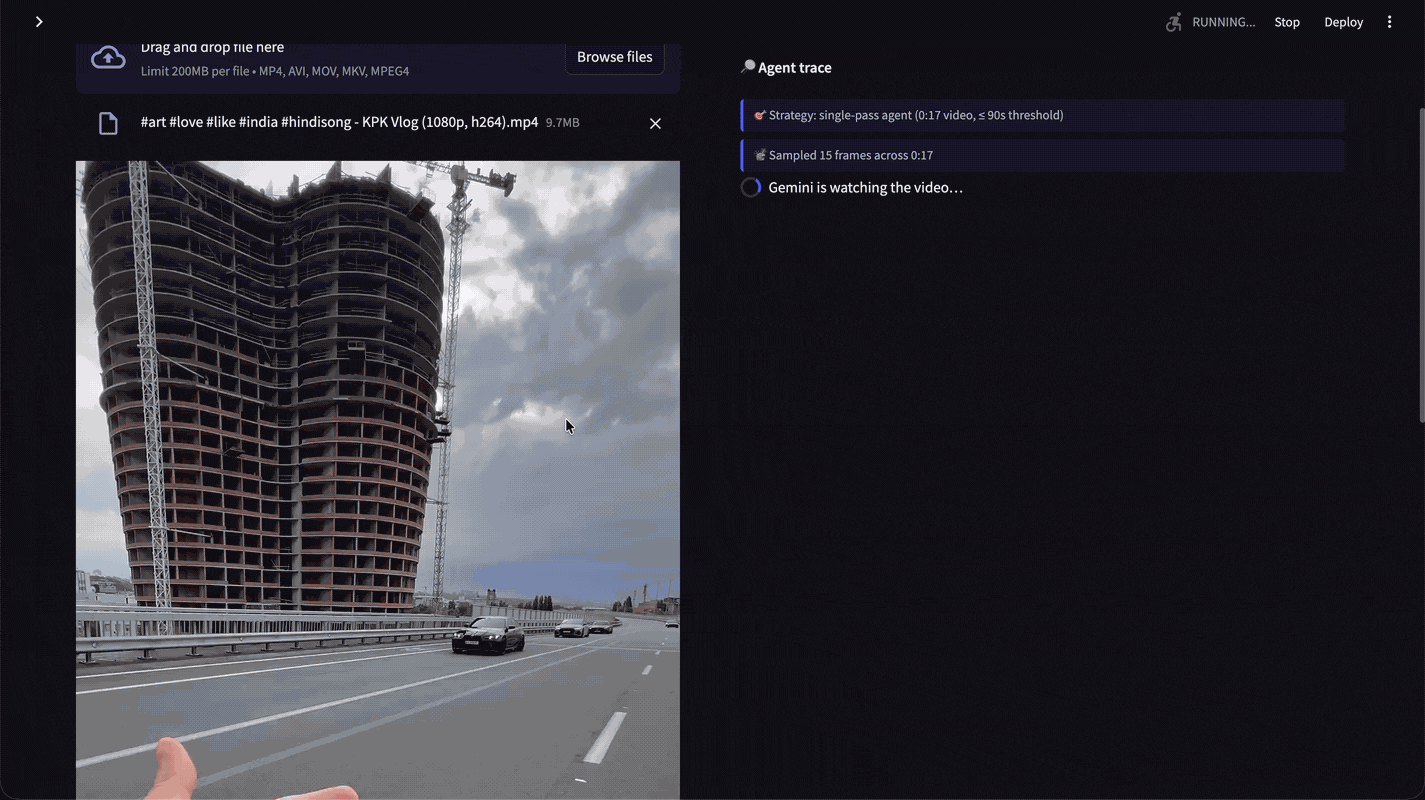
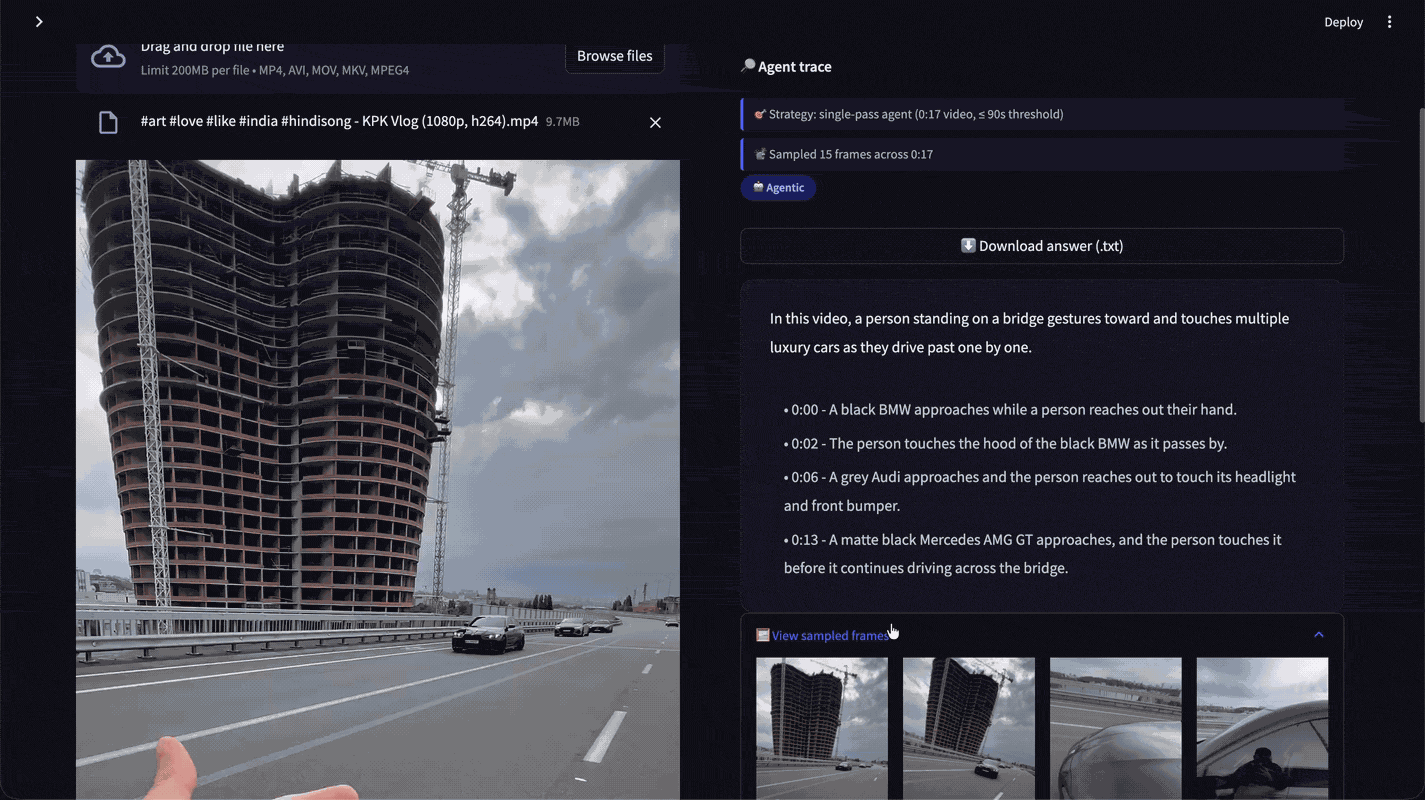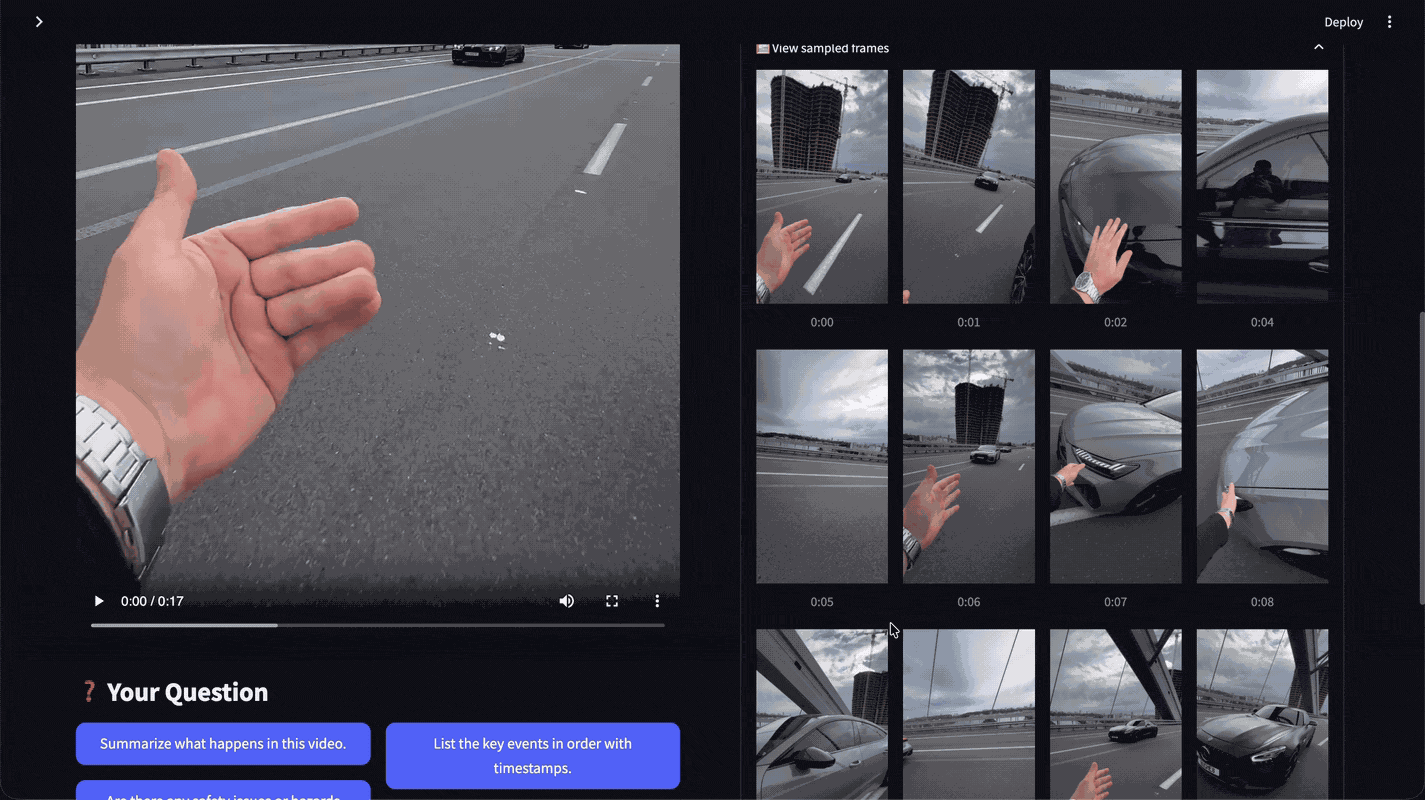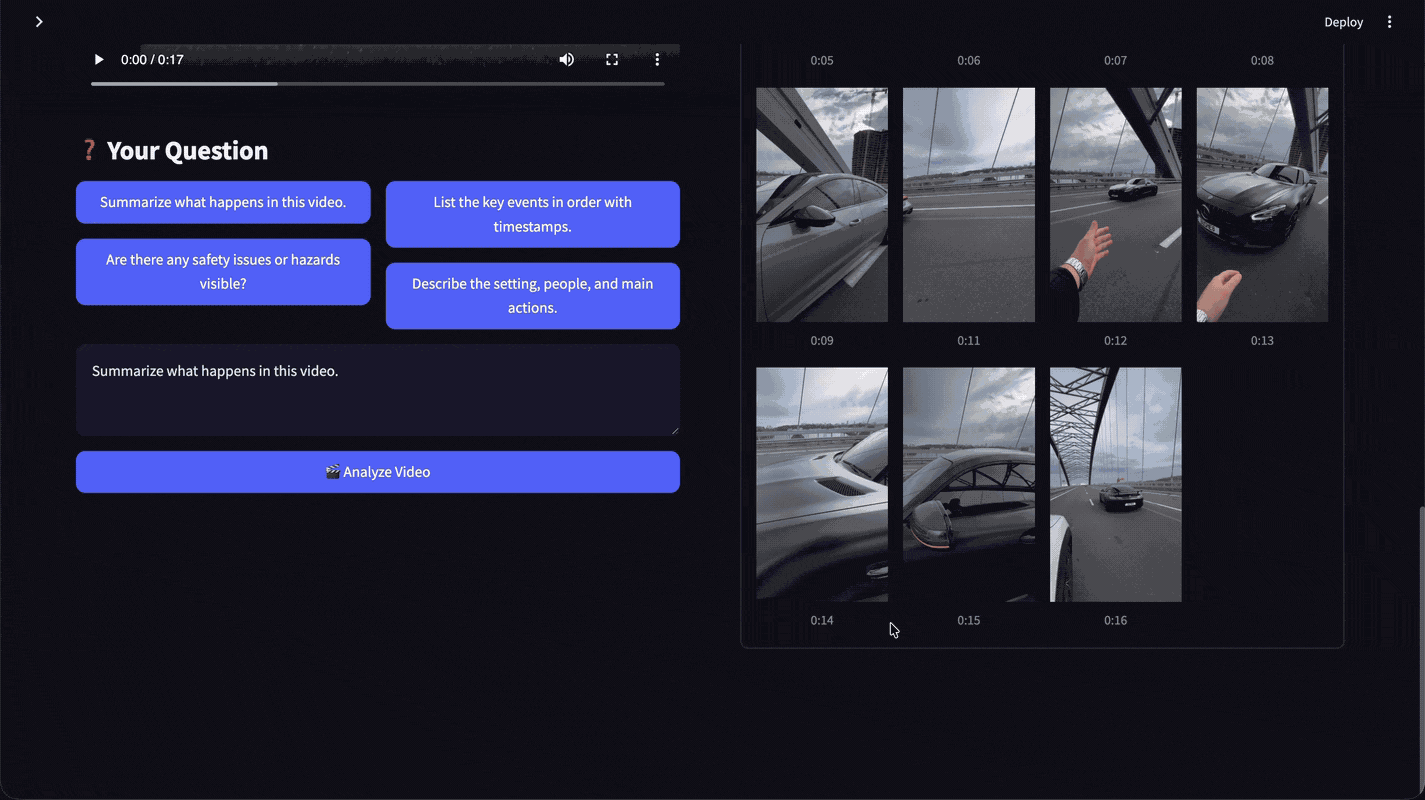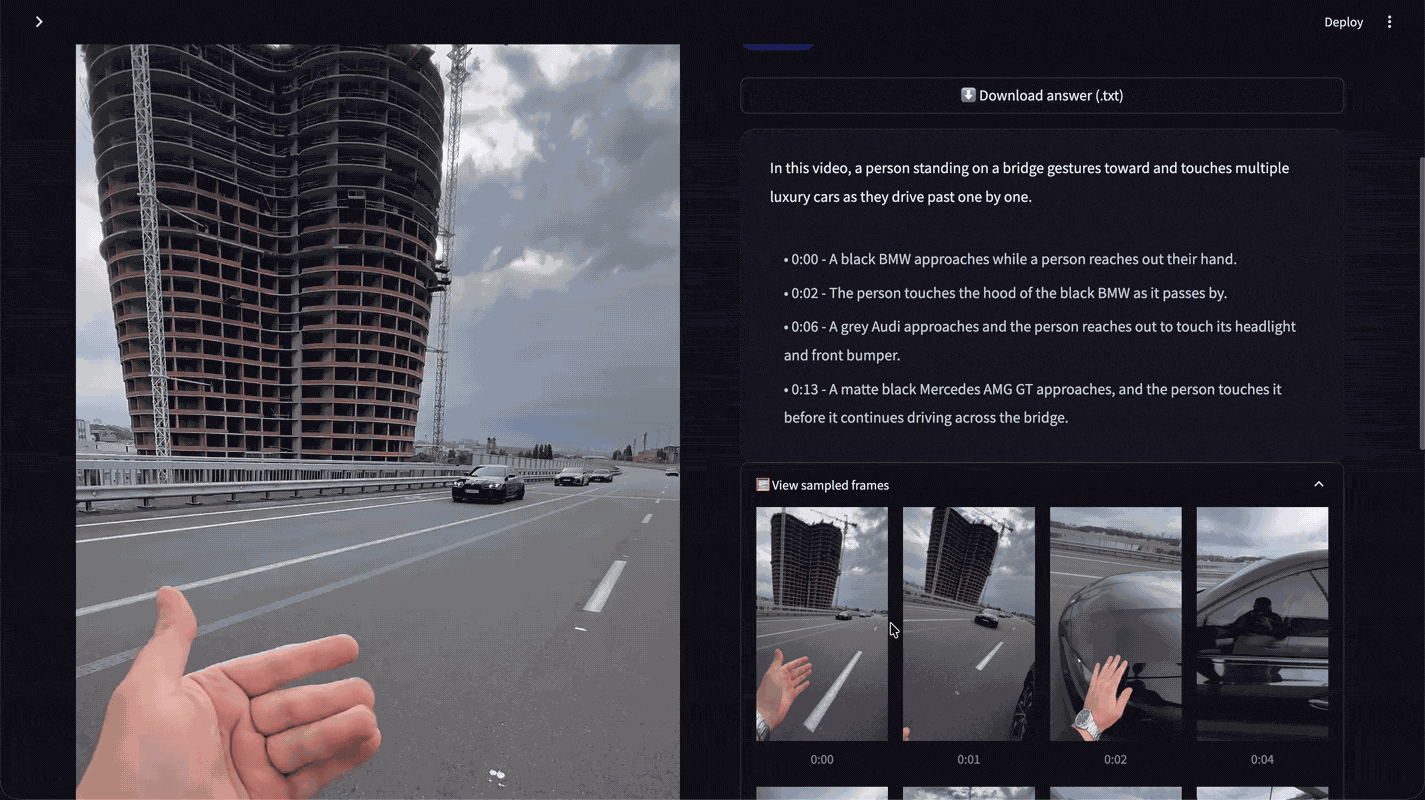
A real tool-use loop, not a single API call wearing an agentic label. The app samples timestamped frames and sends them to Claude with the user's question; Claude decides for itself whether it has enough, and calls zoom_into_segment(start, end) when it needs a closer look. Those frames return inside the tool-result block — the native multi-modal pattern, no extra round trips. Videos over 90 seconds auto-switch to chunk-and-synthesize. Full agent trace visible in the UI.
A bedside vitals monitor split across two microcontrollers on purpose. The PIC18F452 owns acquisition — pulse, ECG, body temperature, room temperature and humidity, and air quality of the room. The ESP8266 owns everything else: the I²C pulse oximeter, UART back to the PIC, serial to a 7" Nextion touch HMI at the bed, and MQTT to Adafruit IO with one feed per parameter and CSV export for records. Sampling doesn't stall when WiFi does. Proteus, then Veroboard, then an etched single-sided PCB.
- PIC18F452 · MikroC
- ESP8266 · Arduino
- Adafruit IO · MQTT
- Nextion HMI · Proteus ARES